After Experiencing a Spike in Access from AI, I Tried Countermeasures That Avoid Blocking AI as Much as Possible, Such as Adjusting robots.txt

This article was published more than one year ago. Please be aware that the information may be outdated.
This page has been translated by machine translation. View original
A spike in access classified under the AI category occurred in the AWS WAF Bot Control rules.
Requests to dynamically generated article pages were recorded at 50,000 per hour, and 1,500 per minute at peak.
This post introduces our investigation into the cause of a volume of requests comparable to the total number of articles published on our site (over 50,000), and the countermeasures we implemented.
Checking CloudWatch Metrics
To identify the cause, we analyzed the AWS WAF metrics.
Surge in bot:category AI
The number of requests in the AI category rose markedly, reaching 50,000 per hour.
No significant fluctuations were observed in other categories (search_engine: Google, Bing, etc.; social_media: X, Facebook, etc.).
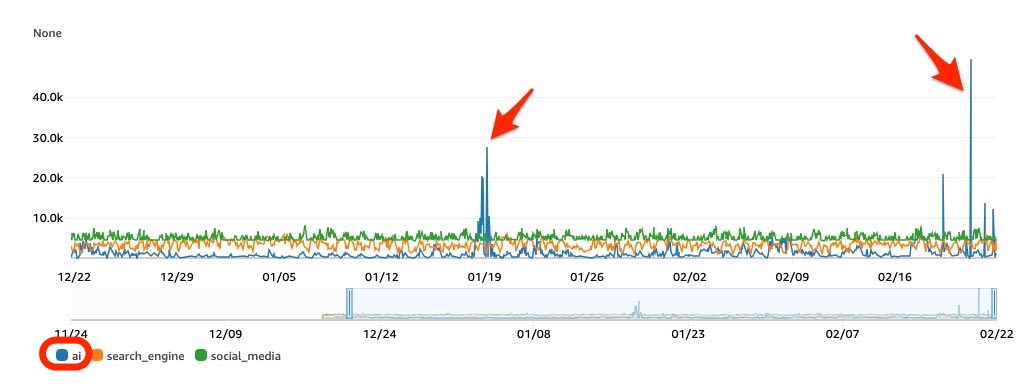
- LabelNamespace="awswaf:managed:aws:bot-control:bot:category"
- LabelName="ai",search_engine, social_media
bot:name claudebot
During the request surge, the "AI" category and the bot:name "ClaudeBot" matched.
From this, we concluded that requests from Anthropic had surged.
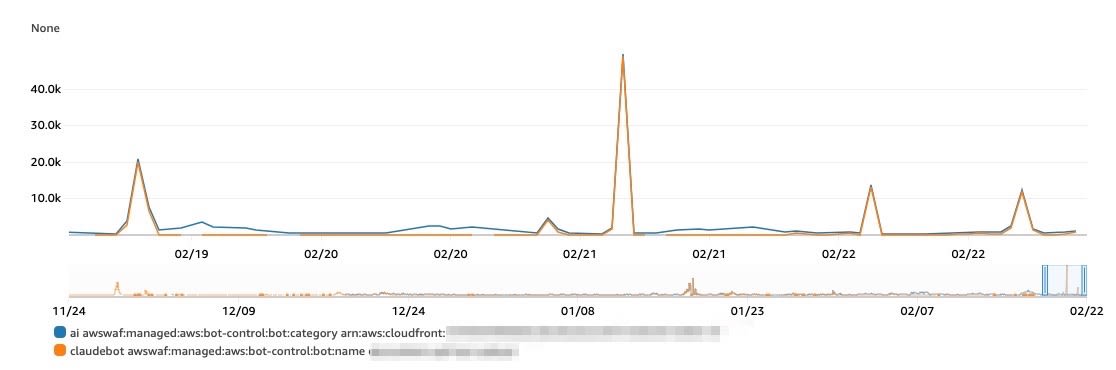
- LabelNamespace="awswaf:managed:aws:bot-control:bot:name"
- LabelName="claudebot"
Access Log Analysis
For more detailed analysis and to consider countermeasures, we analyzed the CloudFront access logs (standard access logs v2) stored in CloudWatch Logs using Logs Insights.
Aggregation by IP and UserAgent
From the access logs during the request surge period, we determined the IP addresses that had the ClaudeBot UserAgent.
fields @timestamp, @message
| parse @message /\"time-taken\":\"(?<timetaken>[^\"]+)\"/
| parse @message /\"c-ip\":\"(?<clientip>[^\"]+)\"/
| parse @message /\"cs\(User-Agent\)\":\"(?<useragent>[^\"]+)\"/
| parse @message /\"x-edge-response-result-type\":\"(?<edge_response_result_type>[^\"]+)\"/
| filter tolower(useragent)  like /claudebot/
| stats count() as request_count,
        sum(timetaken) as total_time,
        avg(timetaken) as avg_time
  by clientip,useragent
| sort request_count desc
| limit 10000
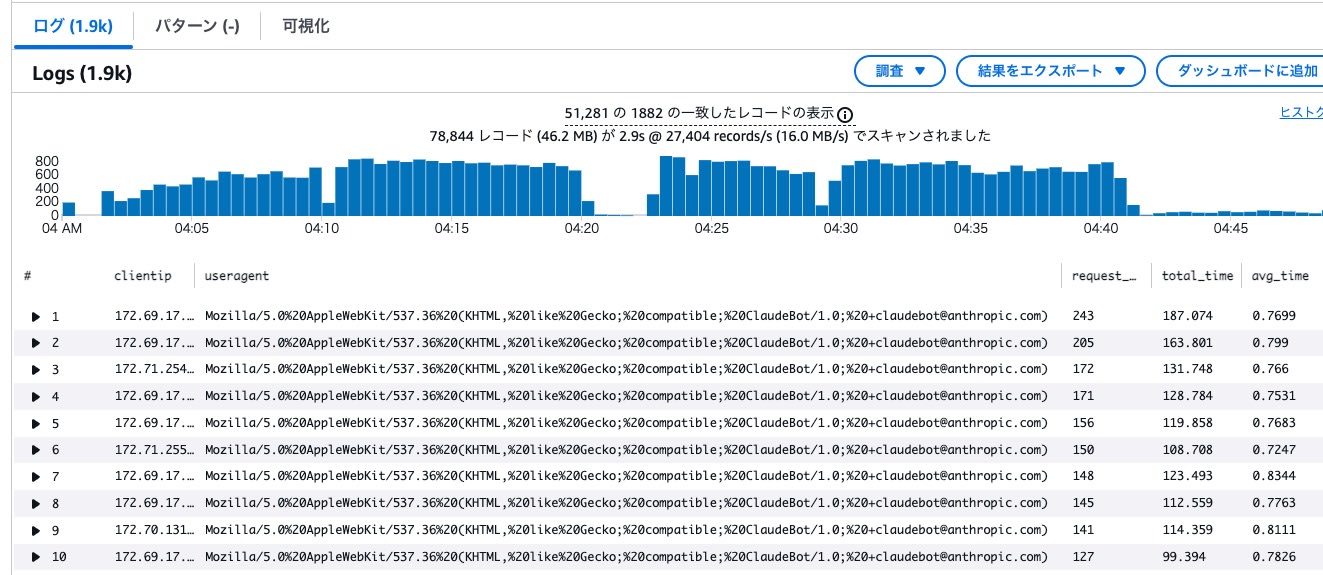
- The number of recorded IPs was 1,888
- Each IP address generated roughly 100 to 200 requests.
Number of Concurrent Access IPs
For the ClaudeBot logs, we checked the number of unique IP addresses per second.
fields @timestamp, @message
| parse @message /\"time-taken\":\"(?<timetaken>[^\"]+)\"/
| parse @message /\"c-ip\":\"(?<clientip>[^\"]+)\"/
| parse @message /\"cs\(User-Agent\)\":\"(?<useragent>[^\"]+)\"/
| filter tolower(useragent) like /claudebot/
| stats count(*) as total_requests,
        count_distinct(clientip) as unique_ips
  by bin(1s)
| sort by unique_ips desc
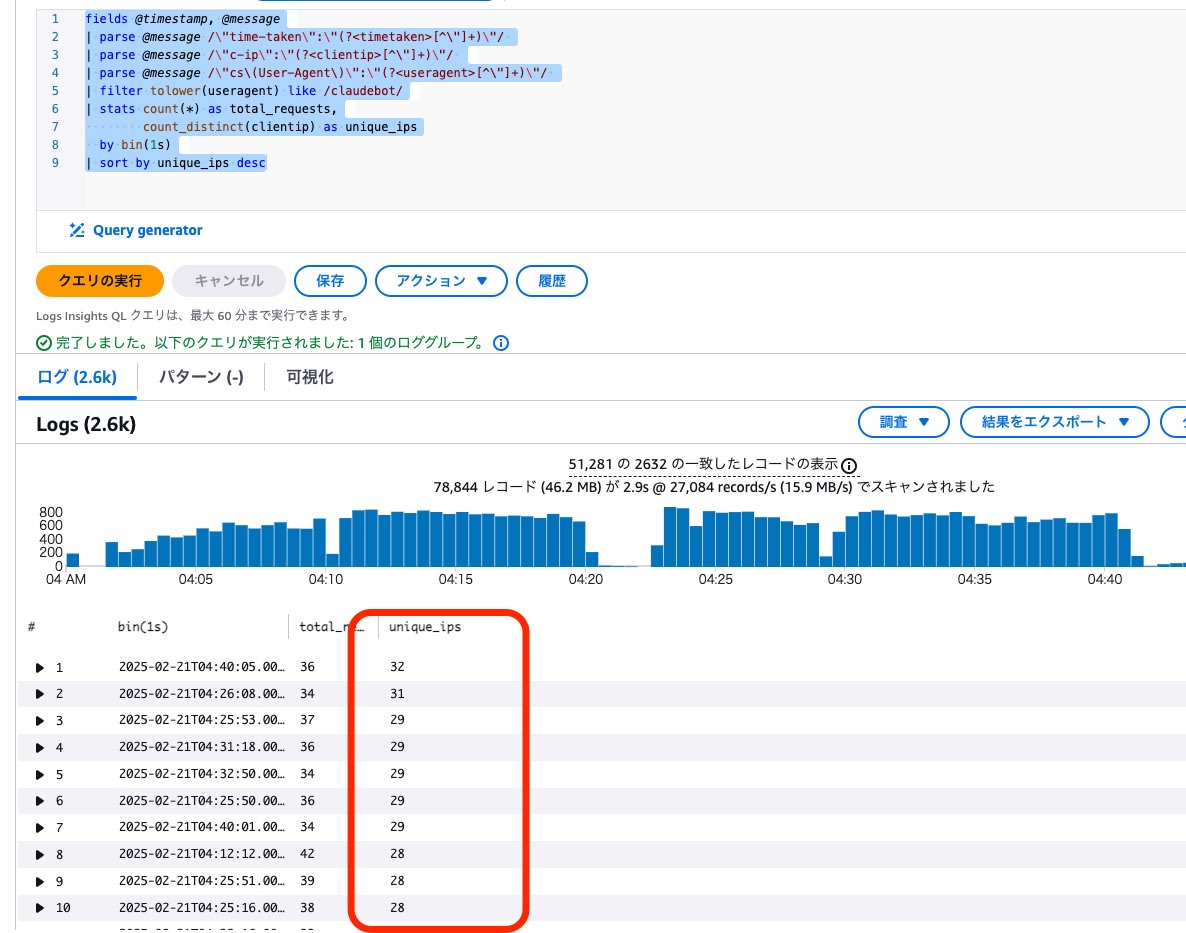
- Up to 32 unique IP addresses accessed simultaneously, suggesting that requests may have been made with a concurrency of around 30.
Aggregation by URL
We attempted to check the requested URIs.
fields @timestamp, @message
| parse @message /\"time-taken\":\"(?<timetaken>[^\"]+)\"/
| parse @message /\"cs\(User-Agent\)\":\"(?<useragent>[^\"]+)\"/
| parse @message /\"cs-uri-stem\":\"(?<uri>[^\"]+)\"/
| parse @message /\"sc-status\":\"(?<status>[^\"]+)\"/
| filter tolower(useragent) like /claudebot/
| stats count() as request_count,
        sum(timetaken) as total_time,
        avg(timetaken) as avg_time
  by uri,useragent, status
| sort total_time desc
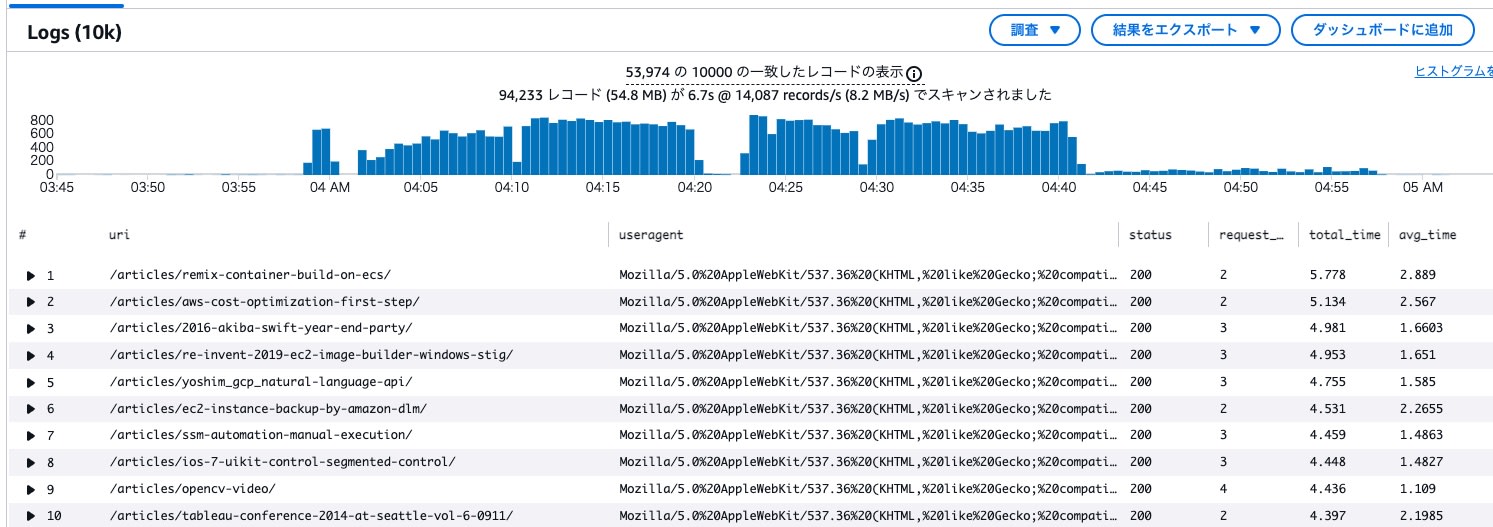
- 25,000 requests to legitimate article pages were confirmed.
Aggregation by x_host_header
Because multiple accesses to the same article were observed, we attempted to aggregate by the requested host (host header).
fields @timestamp, @message
| parse @message /\"time-taken\":\"(?<timetaken>[^\"]+)\"/
| parse @message /\"cs\(User-Agent\)\":\"(?<useragent>[^\"]+)\"/
| parse @message /\"x-host-header\":\"(?<x_host_header>[^\"]+)\"/
| parse @message /\"sc-status\":\"(?<status>[^\"]+)\"/
| filter tolower(useragent) like /claudebot/
| stats count() as request_count,
        sum(timetaken) as total_time,
        avg(timetaken) as avg_time
  by x_host_header,useragent, status
| sort total_time desc
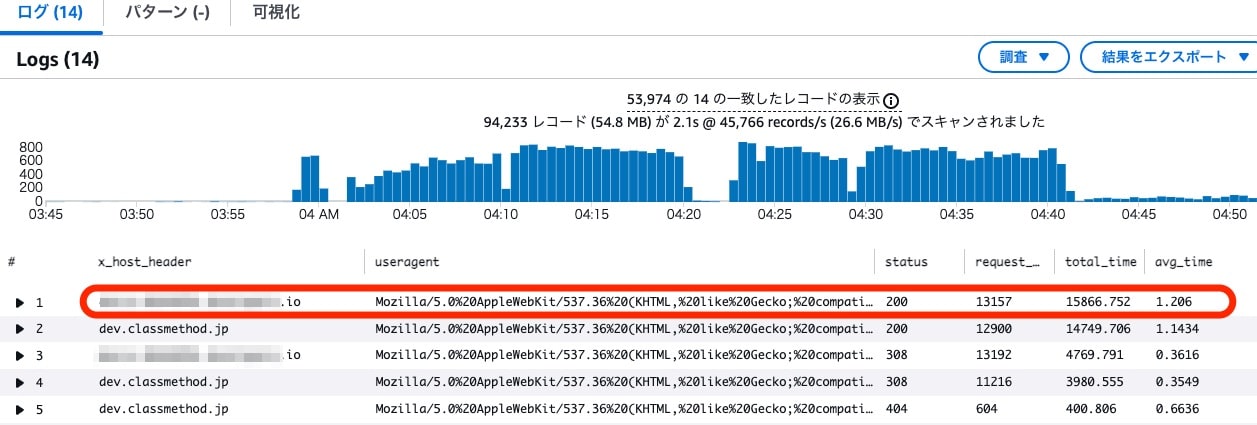
Requests using a hostname different from the hostname of the public URL were confirmed.
Individual Requests
We determined the IP addresses whose UserAgent contained "claudebot" and checked the content of their requests.
fields @timestamp, @message
| parse @message /\"time-taken\":\"(?<timetaken>[^\"]+)\"/
| parse @message /\"c-ip\":\"(?<clientip>[^\"]+)\"/
| parse @message /\"cs\(User-Agent\)\":\"(?<useragent>[^\"]+)\"/
| filter tolower(useragent)  like /claudebot/
| filter clientip  like /172.71.##.##/
| limit 100
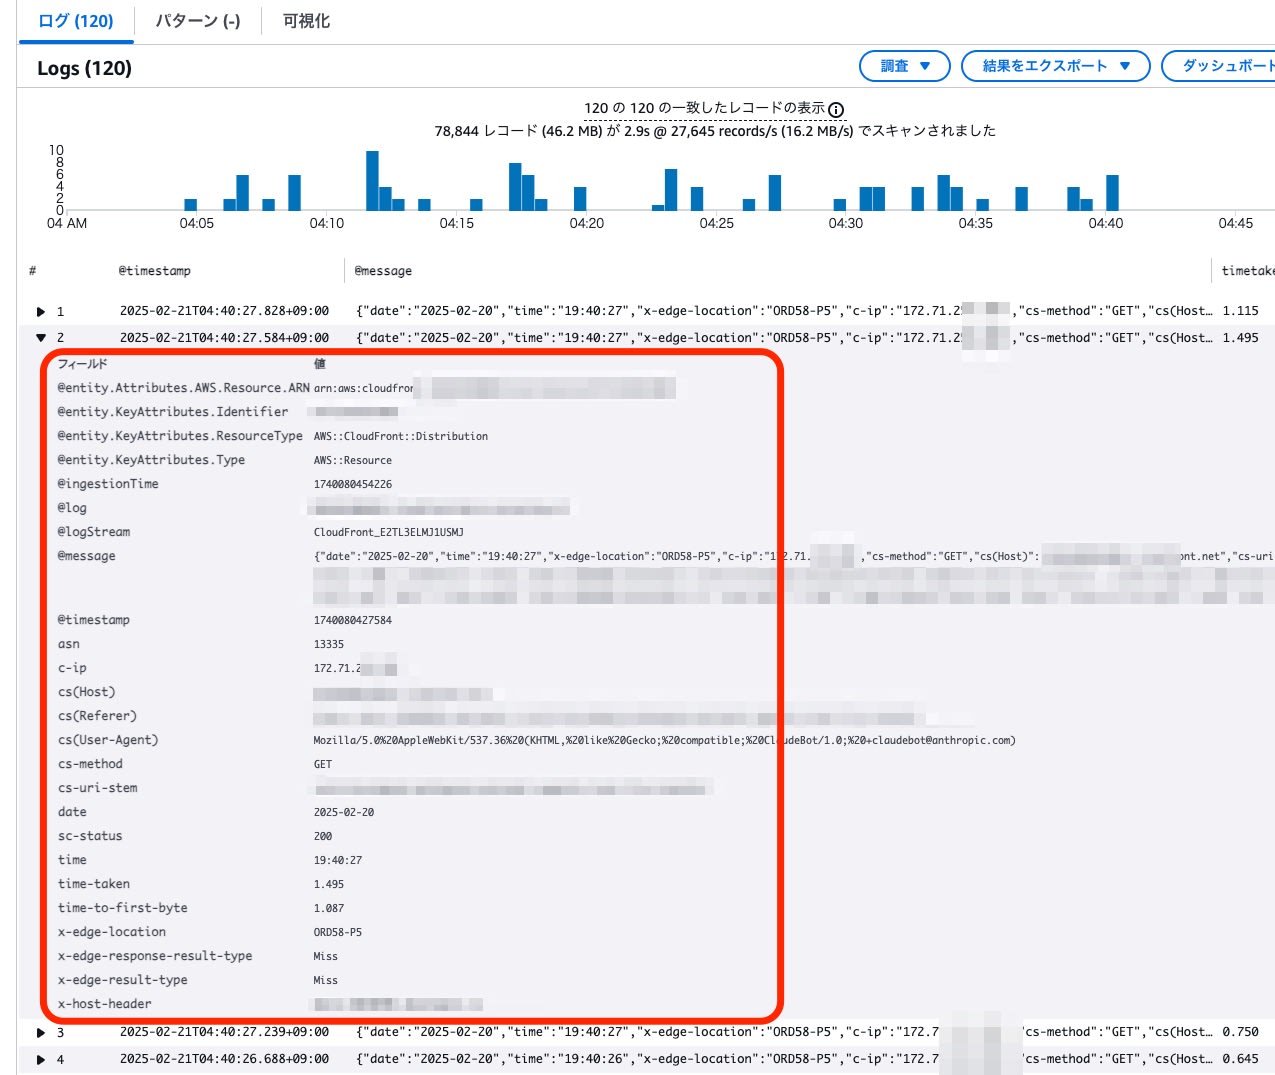
- The number of requests per minute from a single IP address was about 10
Countermeasures
robots.txt
Following Anthropic's guide, we added a setting to robots.txt requesting a 1-second crawl delay (Crawl-delay).
We attempted to describe a rule to curb excessive crawling.
$ curl -s https://dev.classmethod.jp/robots.txt | grep 'Crawl-delay:'
Crawl-delay: 1
We support the non-standard Crawl-delay extension in robots.txt to limit crawling activity. For example:
User-agent: ClaudeBot
Crawl-delay: 1Does Anthropic crawl data from the web, and how can site owners block the crawler?
Alternative Domain
About half of this spike in access was directed at an alternative URL that is not the legitimate public FQDN. This alternative URL had been used for operation verification by stakeholders before the service launched, and for external monitoring of performance after launch.
Previously, we had set "x-robots-tag: noindex".
< HTTP/2 200
< date: Fri, 21 Feb 2025 **:**:** GMT
< content-type: text/plain
(...)
< x-robots-tag: noindex
Since this had no effect on AI crawlers, we adjusted the Cloudflare rules and changed the setting to a 301 redirect to the legitimate site.
< HTTP/2 301
< date: Fri, 21 Feb 2025 **:**:** GMT
< content-type: text/html
(...)
< location: https://dev.classmethod.jp/
After the number of redirects subsides, we plan to retire the FQDN in question.
Block
Using AWS WAF rate-based rules and custom keys, it is possible to block when more than a certain number of requests occur within a specified period.
Our current policy is to avoid blocking as much as possible, but in case the spike in access continues without any effect from robots.txt and the like, we have prepared the following rule so that it can be added to the AWS WAF ACLs.
- Rate limiting using the bot-control determination label (Block is triggered at 100 or more per minute)
{
    "Name": "rate-limit-claudebot",
    "Priority": 250,
    "Statement": {
        "AndStatement": {
            "Statements": [
                {
                    "LabelMatchStatement": {
                        "Scope": "LABEL",
                        "Key": "awswaf:managed:aws:bot-control:bot:name:claudebot"
                    }
                },
                {
                    "RateBasedStatement": {
                        "Limit": 100,
                        "AggregateKeyType": "CUSTOM_KEYS",
                        "CustomKeys": [
                            {
                                "Type": "LABEL_NAMESPACE",
                                "Key": "awswaf:managed:aws:bot-control:bot:name"
                            }
                        ],
                        "TimeWindow": 60
                    }
                }
            ]
        }
    },
    "Action": {
        "Block": {}
    },
    "VisibilityConfig": {
        "SampledRequestsEnabled": true,
        "CloudWatchMetricsEnabled": true,
        "MetricName": "RateLimitClaudeBotRule"
    }
}
Results (added on 2/27)
After updating robots.txt, the number of requests from ClaudeBot decreased to about 20 to 50 per hour.
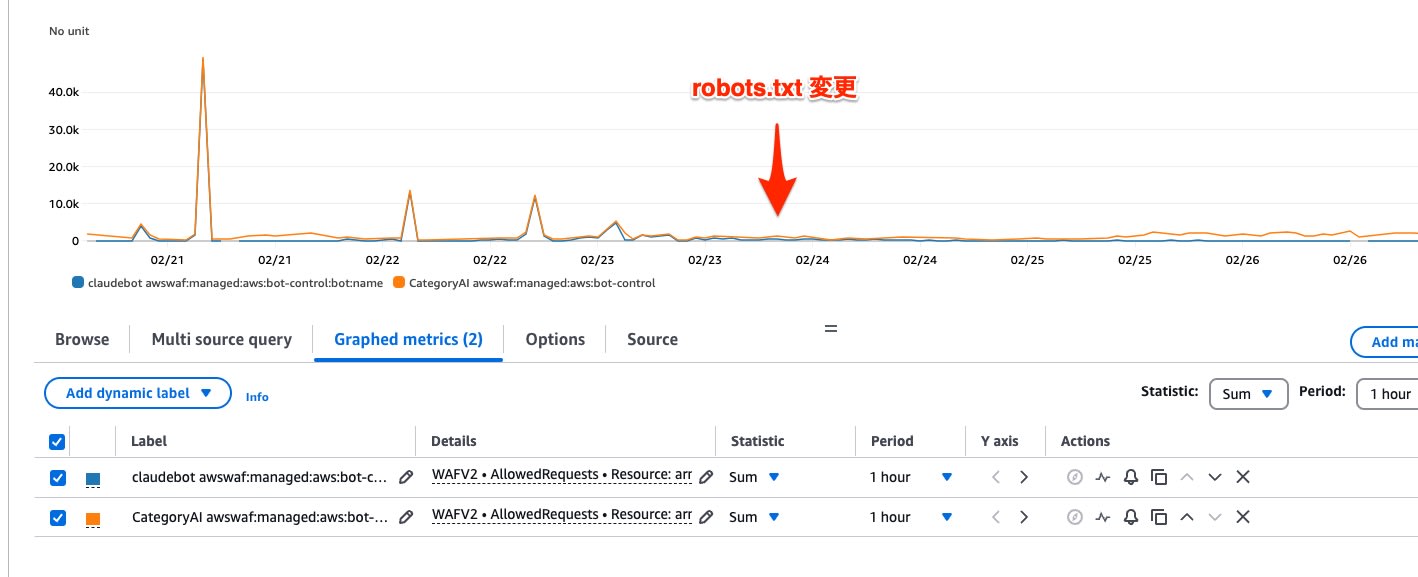
On social media, a case was introduced in which iFixit's site received requests on the scale of one million from ClaudeBot and dealt with it using robots.txt.
Proper robots.txt settings are considered effective for controlling ClaudeBot's crawling.
Summary
Although it is easy to configure AWS WAF to exclude AI agents, doing so could be detrimental to both readers and authors, for example by removing our site's article content from AI-powered search or preventing the latest updates from being reflected, so our policy is to avoid blocking measures as much as possible.
This time we tried controlling crawl frequency with robots.txt, and we have also started preparing "llms.txt", clearly stating instructions for LLMs (large language models) as a measure to guide AI crawlers.
This spike in access also revealed points to improve on the infrastructure side. As future measures, we plan to strengthen the robustness of the entire system through a combined approach, including optimizing the backend systems, using CloudFront's VPC support to prevent direct access to the origin, and advanced AWS WAF configuration.
