Trying Out "Root Volume Replacement" in EC2 Auto Scaling to Update the OS Without Changing the IP or ID

This page has been translated by machine translation. View original
On November 20, 2025, Amazon EC2 Auto Scaling added support for a feature (ReplaceRootVolume) that replaces only the root volume during an instance refresh, without terminating the instance.
For standalone EC2 instances not managed by Auto Scaling, "root volume replacement" had already been supported since 2021.
The point of this update is that this feature has been integrated with the Auto Scaling group "instance refresh" feature. This makes it possible to update the OS across the board "without changing the instance ID" within Auto Scaling's lifecycle management, rather than through manual work.
I actually tested this feature with the AWS CLI and will share the behavior details and downtime, confirmed based on logs.
Overview of the Test and Criteria
The biggest benefit of this feature is that you can swap out only the contents (OS/disk) while keeping the instance itself (instance ID/IP) as is.
Test Environment
- Region: Oregon (us-west-2)
- OS: Amazon Linux 2023 (ARM64)
- Instance type: t4g.nano
- Configuration: Auto Scaling group (Min=1, Max=1)
User Data for the Test
In this test, to tell whether the OS had been reinitialized, I set the following User Data script. When the instance starts (and at the first boot after root volume replacement), it writes "the current time" to Nginx's default page.
#!/bin/bash
# Install and start Nginx
dnf install -y nginx
systemctl start nginx
systemctl enable nginx

# Get metadata and generate index.html
INSTANCE_ID=$(curl -s http://169.254.169.254/latest/meta-data/instance-id)
# Get the current time (whether this gets updated is the key point of the test)
CREATED_AT=$(date -u +"%Y-%m-%d %H:%M:%S UTC")

# Write to the HTML file
cat <<EOF > /usr/share/nginx/html/index.html
Instance ID: ${INSTANCE_ID}
Page Created: ${CREATED_AT}
EOF
Judgment Logic
- ID/IP retained: The instance ID and public IP must not change before and after the update.
- Volume replaced: The "Page Created" time in the HTML returned by Nginx must change to the time when the update was executed.
1. Checking the Initial State
After building the environment with CloudFormation, I checked the state in the Management Console and the CLI.
The instance to be replaced by the instance refresh (root-volume-test-asg-instance) is running normally.
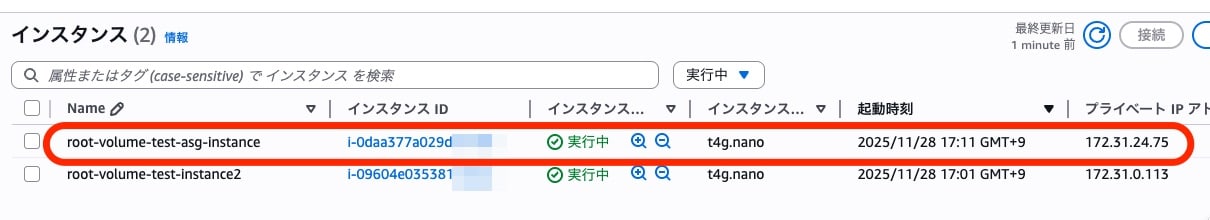
(The upper one is the test target instance under ASG management. ID: i-0daa377a... / Launch time: 17:11 JST)
I sent a request to the public IP address of the running instance and checked the web server's response.
curl http://34.221.xxx.xxx
Result:
Instance ID: i-0daa377a********
Page Created: 2025-11-28 08:12:32 UTC
At this point, the instance ID is i-0daa377a******** and the IP is 34.221.xxx.xxx.
*The console launch time (JST 17:11) and the web page creation time (UTC 08:12) are also consistent.
2. Running the Instance Refresh (CLI)
I created a new AMI (v2) with an updated OS and updated the version of the launch template.
Next, I ran an instance refresh specifying the new ReplaceRootVolume strategy.
An important point here is that using this feature requires a MixedInstancesPolicy (mixed instances policy) configuration. It does not work with a single launch template specification, so I explicitly specified the policy in desired-configuration.
aws autoscaling start-instance-refresh \
  --auto-scaling-group-name root-volume-test-asg \
  --strategy ReplaceRootVolume \
  --desired-configuration '{
    "MixedInstancesPolicy": {
      "LaunchTemplate": {
        "LaunchTemplateSpecification": {
          "LaunchTemplateId": "lt-07681aad********",
          "Version": "2"
        },
        "Overrides": [
          {
            "InstanceType": "t4g.nano",
            "ImageId": "ami-0d937885********"
          }
        ]
      }
    }
  }' \
  --preferences '{"MinHealthyPercentage":0, "InstanceWarmup":300}' \
  --region us-west-2
After running the command, the status changed to InProgress and the update process started.
3. Downtime Measurement Results
While the refresh was running, I ran a script that sent HTTP requests to the target IP address at 10-second intervals and measured the service outage time.
Monitoring log (excerpt):
Timestamp,Status,HTTPCode
2025-11-28 08:13:28,SUCCESS,200
2025-11-28 08:13:38,FAILED,0     <-- 通信断開始
2025-11-28 08:13:48,FAILED,0
2025-11-28 08:14:03,FAILED,0
2025-11-28 08:14:18,FAILED,0
2025-11-28 08:14:33,FAILED,0
2025-11-28 08:14:43,SUCCESS,200  <-- 復旧
Result:
The period during which communication was interrupted was about 50 to 60 seconds.
This is roughly equivalent to the time a t4g.nano instance takes to reboot the OS. In terms of pure OS boot time, there is no big difference from the conventional approach of recreating the instance (Terminate & Launch), but I confirmed that it reliably recovers in about the time of a reboot.
4. Test Results: Checking the ID and Contents
After the update completed, I accessed the instance again and checked the ID and page creation time.
curl http://34.221.xxx.xxx
Result:
Instance ID: i-0daa377a******** <-- 変更なし!
Page Created: 2025-11-28 08:14:35 UTC  <-- 更新された!
Analysis of the Results
- Instance ID/IP retained:
i-0daa377a********and the IP address are unchanged from the initial state. - Root volume replaced: The
Page Createdtime was updated to the time during the refresh process (08:14:35). This proves that the OS booted from the new root volume and the User Data script was re-executed.
Based on the above logs, I concluded that "only the root volume was replaced successfully while keeping the instance ID."
5. In What Cases Does It Speed Things Up?
With a lightweight web server like the one in this test, creating a new instance completes in 1 to 2 minutes, so the time benefit may be hard to feel. However, in environments like the following, where "
changes to the IP address or MAC address are the bottleneck," this feature could dramatically shorten the update time.
- Registration with a license server:
When you use commercial software tied to a MAC address or IP address, and every time the instance changes, procedures such as reissuing the license or deregistering and re-registering it are required. - IP address-based access restrictions:
When firewall settings on the counterpart system must be changed, and an application workflow occurs every time the IP changes. - Large-scale initial provisioning:
When several gigabytes of data must be downloaded after the instance starts, but since the local disk (EBS data volume) can be retained, only a differential update is needed.
Considerations and Constraints
The points to note confirmed through the test are as follows.
- The ASG must be configured with MixedInstancesPolicy:
As also stated in the [Instance Refresh Requirements] section of the official documentation, when using the ReplaceRootVolume strategy, the Auto Scaling group itself must be configured with aMixedInstancesPolicy.
It cannot be used with the common configuration (Standard) that uses a single launch template, so applying it to an existing environment may require changing the ASG settings. - Memory and disk data are lost: Because an OS reboot is involved, memory contents are cleared. Also, since the root volume is replaced entirely, logs and data in the volume are lost. You need to design the system so that necessary data is moved to EBS data volumes or S3.
- User Data is re-executed: Because the root volume is replaced, the cloud-init initialization process (User Data) may be executed again. The script needs to be written with idempotency in mind.
- Instance store is not supported: The root volume must be an EBS volume.
Summary
I tested the ReplaceRootVolume strategy of EC2 Auto Scaling.
- The instance ID, IP address, and MAC address do not change
- Downtime is at the level of an OS reboot (about 50 seconds in this test)
For systems that had given up on using Auto Scaling (making the infrastructure immutable) for reasons such as "a changing IP is a problem" or "license authentication is lost when the MAC address changes," this should become a strong option.
Please give it a try in your test environment.
