I Showed Document Images to Gemini Decision 1 and Had It Look for OCR Errors, Then Compared It with the Jev Decisions API

This page has been translated by machine translation. View original
Hello, I'm Keima.
For OCR processing of documents on AWS, one approach is to host an OCR model on Amazon SageMaker to extract the text, then use a downstream LLM to structure keys and values while making use of the character recognition confidence scores.
However, keeping a model hosted on SageMaker around the clock tends to get expensive, and combining multiple services tends to make the architecture heavy.
Recently, the character recognition accuracy of VLMs themselves has improved, so a setup where a VLM alone handles the whole extraction has become practical.
However, the confidence values an LLM outputs tend to be self-reported, and it can give high scores even to misread values, so they have a weakness: they can't be fully trusted as a basis for judgment.
So if you pass the document image and the extraction results to a decision model and have it judge, per field, with a probability whether "this value matches the image," you can route only the suspicious fields to human review.
Previously, I tried the same thing with Cloudflare's Clef.
For details, please see I showed Cloudflare's Clef document images (Japanese) and had it find errors in OCR results | DevelopersIO.
In this article, I passed document images and OCR values to Gemini Decision 1, which Google released on November 11, 2026, and had it look for errors. I compared it under the same conditions with TypeSafe's Jev, which also supports image input, and OpenAI's Decisions API (the verification date was November 13, 2026). I'm curious how well Google's model, said to be strong at OCR, does.
1. Verification method
1.1 Documents
I used five real documents that can be published in an article.
There are two Japanese and three English documents.
| Document | Language | Source / License |
|---|---|---|
| Receipt from AEON MaxValu Matsuyama store (2019) | Japanese | Wikimedia Commons (public domain) |
| Receipt from CamelMart Akita Hachimantai store (2022) | Japanese | Wikimedia Commons (Yauchi, CC BY-SA 4.0. Reduced to a height of 1400px) |
| Invoice for an open access publishing fee | English | Wikimedia Commons (public domain) |
| US IRS Form 1040 test sample entry (page 2) | English | IRS (US government work) |
| Receipt from a bookstore in Malaysia | English | SROIE (ICDAR 2019) (CC BY 4.0) |
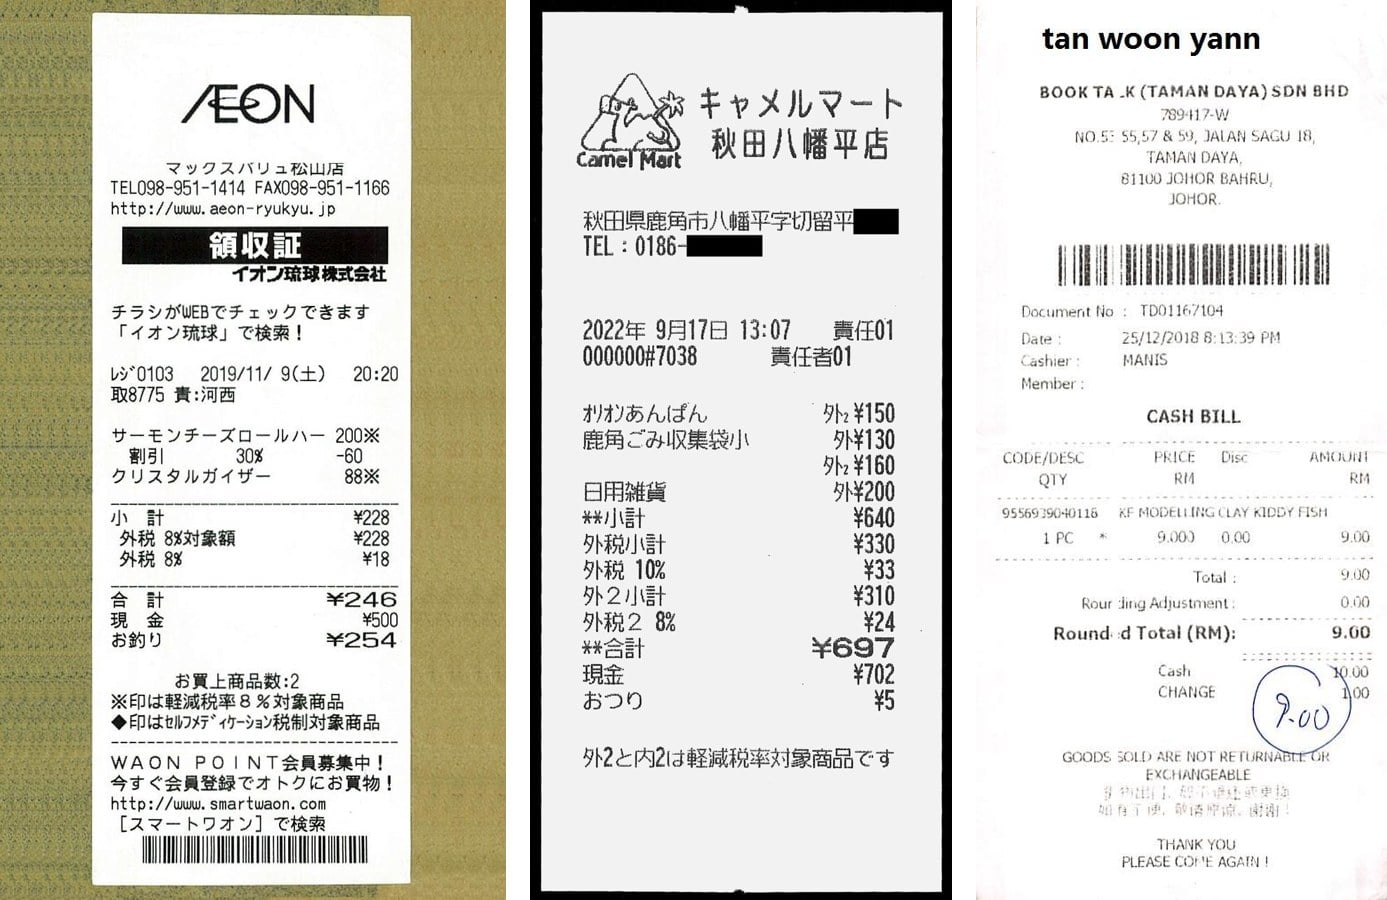
From the left: receipts from AEON MaxValu Matsuyama store, CamelMart Akita Hachimantai store, and a Malaysian bookstore
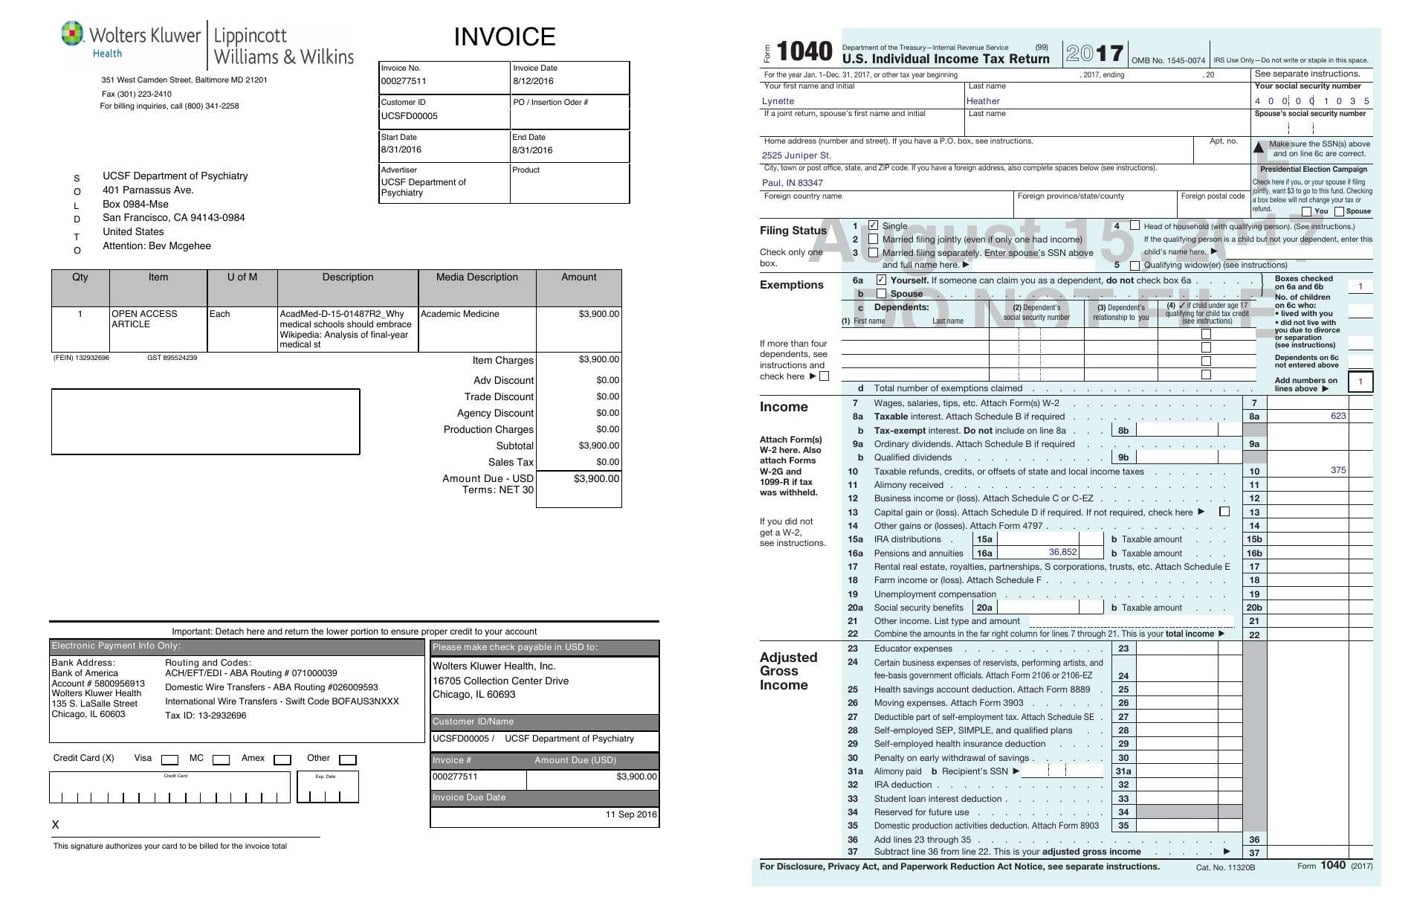
From the left: the open access publishing fee invoice, and page 2 of the Form 1040 test sample entry
The source and license of each image are as shown in the table above. All were reduced in size on this blog and combined side by side into a single image.
1.2 OCR values and deliberately inserted errors
From each document I selected 5 to 6 fields and transcribed the correct values (for example, for the AEON receipt: store name, date, 8% tax, total, change, and so on).
I limited it to some fields rather than the whole document so that the amount of ground-truth data could be reliably checked by hand.
I prepared the following three patterns as verification data.
-
No errors: the transcribed correct values as they are
-
Error A and Error B: versions in which the values of two fields each were deliberately changed
There were three types of error insertion, and I created a total of 20 errors across the 5 documents.
-
Swapped or missing digits (
¥246→¥264,36,852→36,582) -
Replacement with similar-looking characters (
マックスバリュ→マックスバリユ,UCSFD00005→UCSFDO0005) -
Replacement with a different value (the deposit amount
¥500in the change field)
1.3 Questions
I passed the image together with the list of values to the model and asked yes/no questions like the following for each field.
{
  "field__total": {
    "type": "noul",
    "instructions": "抽出した「total」の値 \"¥264\" は、画像に印字されている内容と1文字も違わず同じか。空白の数の違いだけは同じとみなす。"
  }
}
I sent a total of 15 requests (5 documents × 3 patterns) to each of the three models, using the same images and the same questions.
Because image input for Jev is a preview feature, I added the header TypeSafe-Danger-Zone-Images: true and included the images in assets when sending.
1.4 Metrics
-
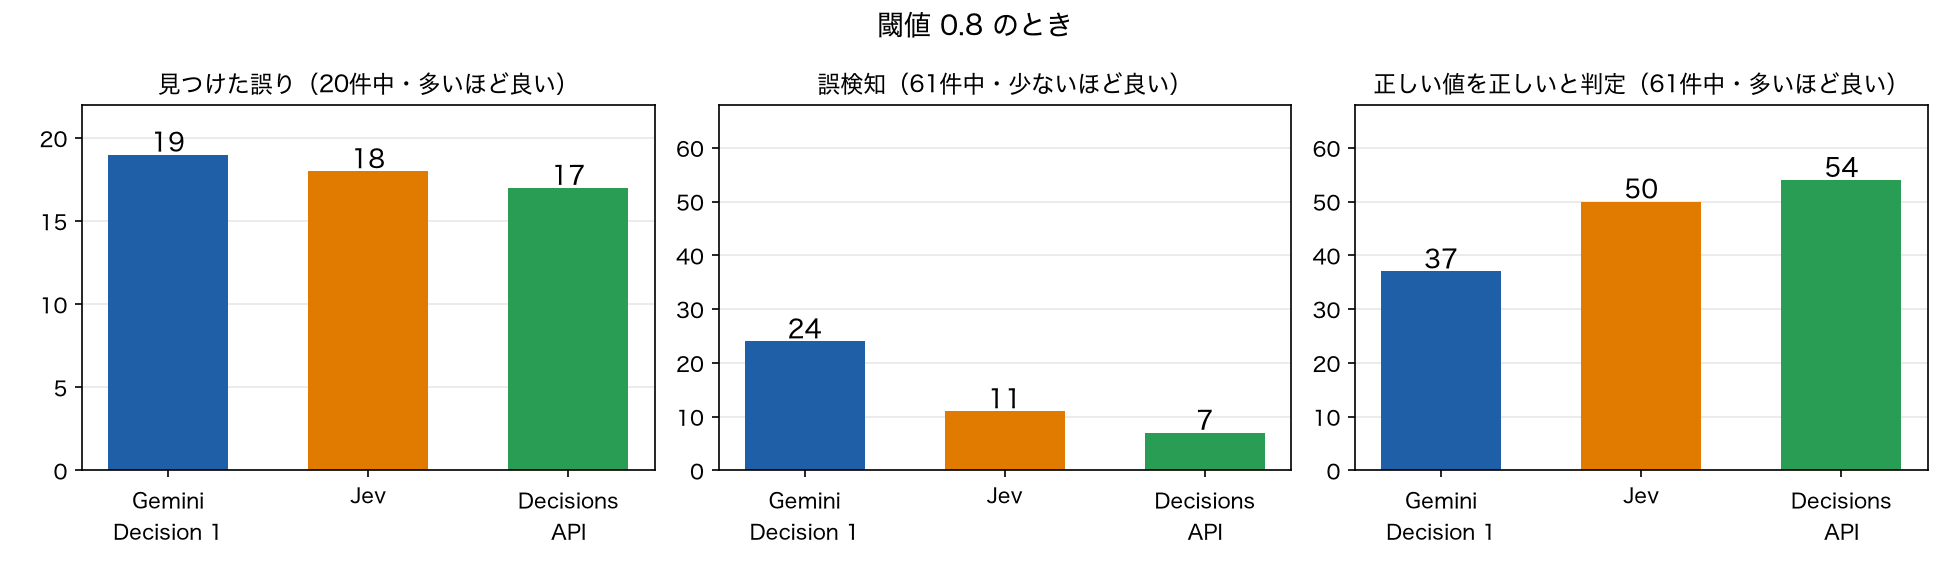
Errors found: Of the 20 pre-inserted errors, the number judged to have a probability of being "the same as the image" below 0.8
-
False positives: Of the 61 correct values, the number whose probability of being "the same as the image" ended up below 0.8 (the more there are, the more fields have to be reviewed by humans)
-
Correct values judged correct: Of the 61 correct values, the number judged to have a probability of being "the same as the image" of 0.8 or higher (together with the false positives this totals 61. Answering "error" for everything would increase the errors found, so I also look at whether correct values were properly passed through)
For the judgment, I used the probabilities before rounding to two decimal places for display (so even a value shown as 0.90 in a table may be "below 0.9" at a threshold of 0.9).
2. Results
2.1 Errors found, false positives, and correct values judged correct
| Item | Gemini Decision 1 | Jev | Decisions API |
|---|---|---|---|
| Errors found (out of 20) | 19 | 18 | 17 |
| of which Japanese (out of 8) | 8 | 8 | 7 |
| False positives (out of 61 correct values) | 24 | 11 | 7 |
| Correct values judged correct (out of 61) | 37 | 50 | 54 |
| Median response time | approx. 1.12 s | approx. 0.31 s | approx. 0.63 s |
| Input tokens (average per request) | 1,749 | 3,268 | 2,257 |
Gemini Decision 1 missed the fewest errors, but it also judged 24 correct values to be errors, and only 37 of the 61 correct values were judged correct.
The number of correct values judged correct was 54 for Decisions API and 50 for Jev.
Most of the false positive cases were ones where it output a probability of around 0.5 to 0.8 for a correct value.
For example, for the store name on the SROIE receipt (BOOK TA .K (TAMAN DAYA) SDN BHD), it output a probability of 0.26 to 0.38 even though the value was correct (this part of the print is faded and hard to read, and Jev and Decisions API also gave below 0.8 for it).
2.2 When changing the threshold
Since the probabilities from Gemini Decision 1 tended to come out lower even for correct values, I changed the judgment threshold and compared.
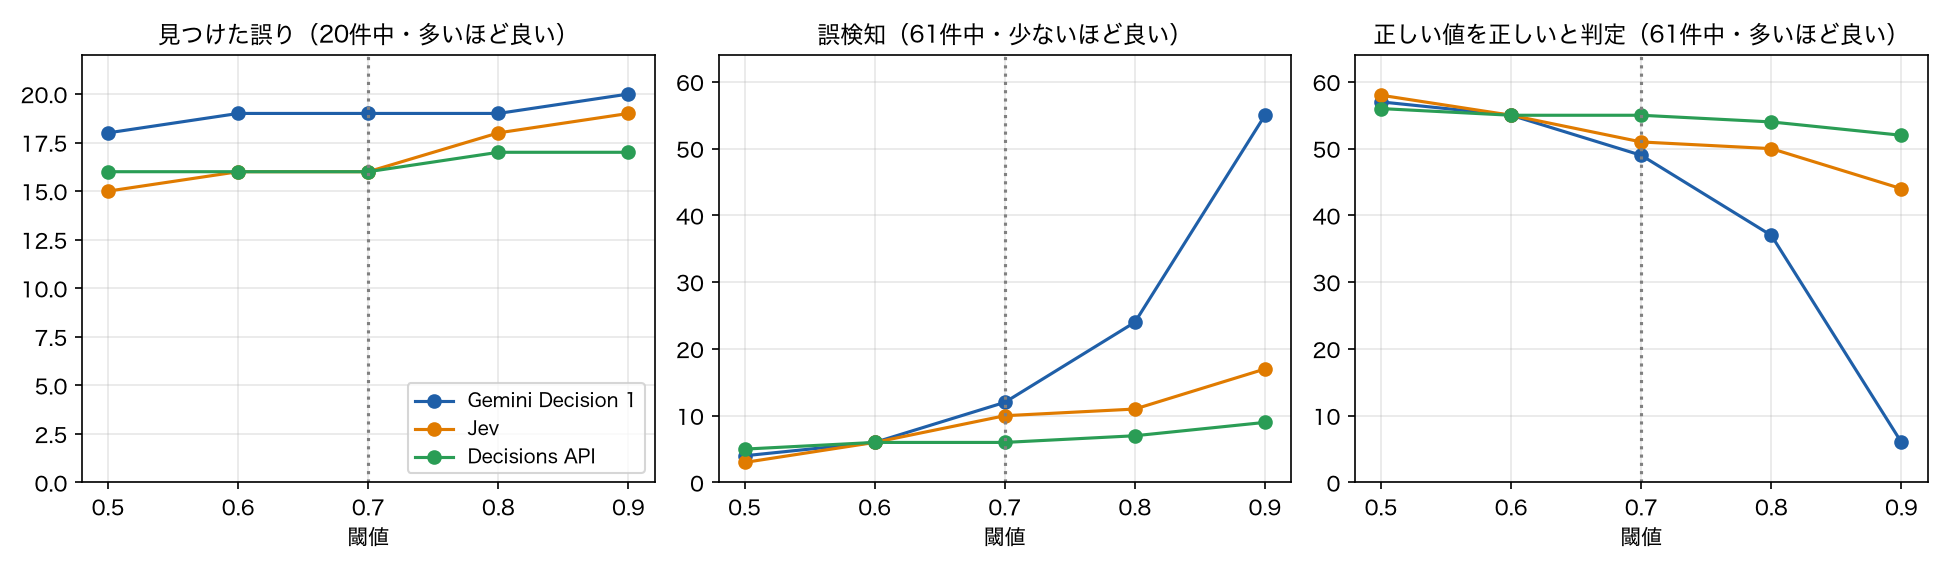
The numbers in the table represent errors found / false positives / correct values judged correct.
| Threshold | Gemini Decision 1 | Jev | Decisions API |
|---|---|---|---|
| 0.5 | 18/4/57 | 15/3/58 | 16/5/56 |
| 0.6 | 19/6/55 | 16/6/55 | 16/6/55 |
| 0.7 | 19/12/49 | 16/10/51 | 16/6/55 |
| 0.8 | 19/24/37 | 18/11/50 | 17/7/54 |
| 0.9 | 20/55/6 | 19/17/44 | 17/9/52 |
With Gemini Decision 1, raising the threshold to 0.8 or 0.9 drastically reduces the number of correct values judged correct (out of 61: 37 at 0.8, 6 at 0.9).
On the other hand, few errors slip through at any threshold, and at 0.6 to 0.8 it detected 19 of the 20 errors.
Looking at this graph, I felt that setting the threshold for Gemini Decision 1 to around 0.7 would give a good balance.
2.3 Missed errors
Here are the errors that at least one of the three models missed.
The numbers are the probability of being "the same as the image," and bold means 0.8 or higher at the threshold, that is, an error that was missed.
| Document | Field | Value passed | Correct value | Gemini Decision 1 | Jev | Decisions API |
|---|---|---|---|---|---|---|
| IRS tax return | First name | Lynnette |
Lynette |
0.90 | 0.98 | 0.00 |
| IRS tax return | 16a Pensions | 36,582 |
36,852 |
0.48 | 0.87 | 1.00 |
| CamelMart | Date | 2022年9月7日 13:07 |
2022年9月17日 13:07 |
0.12 | 0.00 | 0.99 |
| Open access publishing fee invoice | Customer ID | UCSFDO0005 |
UCSFD00005 |
0.41 | 0.15 | 1.00 |
For the error in the tax return's name with one extra n, both Gemini Decision 1 and Jev missed it.
Decisions API, on the other hand, judged errors such as reordered digits and the difference between 0 and O as "the same" with a probability of 1.00.
3. Full results
Here are the results. Bold indicates items whose judgment was wrong under the threshold of 0.8.
| Document | Version | Field | Value passed | Correct value | Gemini | Jev | Decisions API |
|---|---|---|---|---|---|---|---|
| aeon | No errors | store | マックスバリュ松山店 |
マックスバリュ松山店 |
0.83 | 0.64 | 0.99 |
| aeon | No errors | date | 2019/11/9(土) 20:20 |
2019/11/9(土) 20:20 |
0.50 | 0.70 | 1.00 |
| aeon | No errors | tax_8 | ¥18 |
¥18 |
0.86 | 0.94 | 1.00 |
| aeon | No errors | total | ¥246 |
¥246 |
0.85 | 0.98 | 1.00 |
| aeon | No errors | change | ¥254 |
¥254 |
0.83 | 0.96 | 1.00 |
| aeon | Error A | store | マックスバリユ松山店 (error) |
マックスバリュ松山店 |
0.52 | 0.74 | 0.00 |
| aeon | Error A | date | 2019/11/9(土) 20:20 |
2019/11/9(土) 20:20 |
0.48 | 0.60 | 1.00 |
| aeon | Error A | tax_8 | ¥18 |
¥18 |
0.88 | 0.97 | 1.00 |
| aeon | Error A | total | ¥264 (error) |
¥246 |
0.13 | 0.00 | 0.00 |
| aeon | Error A | change | ¥254 |
¥254 |
0.86 | 0.98 | 0.94 |
| aeon | Error B | store | マックスバリュ松山店 |
マックスバリュ松山店 |
0.91 | 0.60 | 0.10 |
| aeon | Error B | date | 2019/11/8(土) 20:20 (error) |
2019/11/9(土) 20:20 |
0.08 | 0.01 | 0.00 |
| aeon | Error B | tax_8 | ¥18 |
¥18 |
0.78 | 0.95 | 1.00 |
| aeon | Error B | total | ¥246 |
¥246 |
0.79 | 0.98 | 1.00 |
| aeon | Error B | change | ¥500 (error) |
¥254 |
0.20 | 0.02 | 0.00 |
| camel | No errors | store | キャメルマート 秋田八幡平店 |
キャメルマート 秋田八幡平店 |
0.81 | 0.96 | 1.00 |
| camel | No errors | date | 2022年9月17日 13:07 |
2022年9月17日 13:07 |
0.80 | 0.95 | 1.00 |
| camel | No errors | tax_10 | ¥33 |
¥33 |
0.82 | 0.97 | 1.00 |
| camel | No errors | tax_8 | ¥24 |
¥24 |
0.72 | 0.88 | 1.00 |
| camel | No errors | total | ¥697 |
¥697 |
0.84 | 0.99 | 1.00 |
| camel | No errors | cash | ¥702 |
¥702 |
0.81 | 0.98 | 1.00 |
| camel | Error A | store | キャメレマート 秋田八幡平店 (error) |
キャメルマート 秋田八幡平店 |
0.47 | 0.50 | 0.06 |
| camel | Error A | date | 2022年9月17日 13:07 |
2022年9月17日 13:07 |
0.77 | 0.96 | 1.00 |
| camel | Error A | tax_10 | ¥38 (error) |
¥33 |
0.05 | 0.00 | 0.00 |
| camel | Error A | tax_8 | ¥24 |
¥24 |
0.77 | 0.97 | 0.97 |
| camel | Error A | total | ¥697 |
¥697 |
0.83 | 0.99 | 1.00 |
| camel | Error A | cash | ¥702 |
¥702 |
0.75 | 0.99 | 1.00 |
| camel | Error B | store | キャメルマート 秋田八幡平店 |
キャメルマート 秋田八幡平店 |
0.83 | 0.98 | 1.00 |
| camel | Error B | date | 2022年9月7日 13:07 (error) |
2022年9月17日 13:07 |
0.12 | 0.00 | 0.99 |
| camel | Error B | tax_10 | ¥33 |
¥33 |
0.84 | 0.98 | 1.00 |
| camel | Error B | tax_8 | ¥24 |
¥24 |
0.67 | 0.94 | 0.95 |
| camel | Error B | total | ¥697 |
¥697 |
0.77 | 0.99 | 1.00 |
| camel | Error B | cash | ¥697 (error) |
¥702 |
0.11 | 0.01 | 0.00 |
| wiki | No errors | invoice_no | 000277511 |
000277511 |
0.90 | 0.89 | 1.00 |
| wiki | No errors | invoice_date | 8/12/2016 |
8/12/2016 |
0.89 | 0.94 | 1.00 |
| wiki | No errors | customer_id | UCSFD00005 |
UCSFD00005 |
0.93 | 0.88 | 1.00 |
| wiki | No errors | amount_due | $3,900.00 |
$3,900.00 |
0.85 | 0.91 | 1.00 |
| wiki | No errors | due_date | 11 Sep 2016 |
11 Sep 2016 |
0.86 | 0.88 | 1.00 |
| wiki | Error A | invoice_no | 000277517 (error) |
000277511 |
0.29 | 0.00 | 0.00 |
| wiki | Error A | invoice_date | 8/12/2016 |
8/12/2016 |
0.69 | 0.96 | 1.00 |
| wiki | Error A | customer_id | UCSFDO0005 (error) |
UCSFD00005 |
0.41 | 0.15 | 1.00 |
| wiki | Error A | amount_due | $3,900.00 |
$3,900.00 |
0.75 | 0.92 | 1.00 |
| wiki | Error A | due_date | 11 Sep 2016 |
11 Sep 2016 |
0.82 | 0.95 | 1.00 |
| wiki | Error B | invoice_no | 000277511 |
000277511 |
0.85 | 0.86 | 1.00 |
| wiki | Error B | invoice_date | 8/12/2016 |
8/12/2016 |
0.72 | 0.91 | 1.00 |
| wiki | Error B | customer_id | UCSFD00005 |
UCSFD00005 |
0.88 | 0.87 | 1.00 |
| wiki | Error B | amount_due | $3,600.00 (error) |
$3,900.00 |
0.09 | 0.00 | 0.00 |
| wiki | Error B | due_date | 8/31/2016 (error) |
11 Sep 2016 |
0.17 | 0.00 | 0.00 |
| irs | No errors | first_name | Lynette |
Lynette |
0.93 | 0.99 | 1.00 |
| irs | No errors | last_name | Heather |
Heather |
0.90 | 0.98 | 1.00 |
| irs | No errors | address | 2525 Juniper St. |
2525 Juniper St. |
0.84 | 0.97 | 1.00 |
| irs | No errors | line_8a_taxable_interest | 623 |
623 |
0.88 | 0.98 | 0.73 |
| irs | No errors | line_10_tax_refunds | 375 |
375 |
0.86 | 0.95 | 1.00 |
| irs | No errors | line_16a_pensions | 36,852 |
36,852 |
0.81 | 0.94 | 1.00 |
| irs | Error A | first_name | Lynnette (error) |
Lynette |
0.90 | 0.98 | 0.00 |
| irs | Error A | last_name | Heather |
Heather |
0.85 | 0.98 | 0.88 |
| irs | Error A | address | 2525 Juniper St. |
2525 Juniper St. |
0.81 | 0.97 | 1.00 |
| irs | Error A | line_8a_taxable_interest | 623 |
623 |
0.86 | 0.98 | 0.96 |
| irs | Error A | line_10_tax_refunds | 375 |
375 |
0.80 | 0.96 | 1.00 |
| irs | Error A | line_16a_pensions | 36,582 (error) |
36,852 |
0.48 | 0.87 | 1.00 |
| irs | Error B | first_name | Lynette |
Lynette |
0.92 | 0.99 | 1.00 |
| irs | Error B | last_name | Heather |
Heather |
0.88 | 0.98 | 1.00 |
| irs | Error B | address | 2552 Juniper St. (error) |
2525 Juniper St. |
0.09 | 0.02 | 0.00 |
| irs | Error B | line_8a_taxable_interest | 375 (error) |
623 |
0.08 | 0.00 | 0.00 |
| irs | Error B | line_10_tax_refunds | 375 |
375 |
0.64 | 0.96 | 0.83 |
| irs | Error B | line_16a_pensions | 36,852 |
36,852 |
0.77 | 0.90 | 0.98 |
| sroie | No errors | company | BOOK TA .K (TAMAN DAYA) SDN BHD |
BOOK TA .K (TAMAN DAYA) SDN BHD |
0.26 | 0.61 | 0.14 |
| sroie | No errors | document_no | TD01167104 |
TD01167104 |
0.89 | 0.05 | 0.57 |
| sroie | No errors | date | 25/12/2018 8:13:39 PM |
25/12/2018 8:13:39 PM |
0.79 | 0.26 | 1.00 |
| sroie | No errors | total | 9.00 |
9.00 |
0.64 | 0.97 | 1.00 |
| sroie | No errors | cash | 10.00 |
10.00 |
0.77 | 0.92 | 1.00 |
| sroie | Error A | company | BOOK TA .K (TAMAN DAYA) SDN BHD |
BOOK TA .K (TAMAN DAYA) SDN BHD |
0.31 | 0.58 | 0.07 |
| sroie | Error A | document_no | TD01161704 (error) |
TD01167104 |
0.35 | 0.00 | 0.18 |
| sroie | Error A | date | 25/12/2018 8:13:39 PM |
25/12/2018 8:13:39 PM |
0.69 | 0.52 | 1.00 |
| sroie | Error A | total | 9.08 (error) |
9.00 |
0.11 | 0.00 | 0.00 |
| sroie | Error A | cash | 10.00 |
10.00 |
0.66 | 0.95 | 1.00 |
| sroie | Error B | company | BOOK TA .K (TAMAN DAYA) SDN BHD |
BOOK TA .K (TAMAN DAYA) SDN BHD |
0.38 | 0.57 | 0.42 |
| sroie | Error B | document_no | TD01167104 |
TD01167104 |
0.89 | 0.13 | 0.33 |
| sroie | Error B | date | 25/12/2018 8:18:39 PM (error) |
25/12/2018 8:13:39 PM |
0.14 | 0.00 | 0.78 |
| sroie | Error B | total | 9.00 |
9.00 |
0.60 | 0.99 | 1.00 |
| sroie | Error B | cash | 1.00 (error) |
10.00 |
0.22 | 0.71 | 0.00 |
4. Summary
I passed images of five documents and their OCR values to Gemini Decision 1, Jev, and Decisions API, and had them look for the deliberately inserted errors.
Gemini Decision 1 can also find errors in OCR values.
Also, even when given the same images, it used fewer input tokens than the other two models.
I got the same result when I tested a Gemini model before, so this may be a characteristic of Gemini-family models.
It feels like it could be used at a practical level for Japanese documents as well.
However, its sense of thresholds differs from Jev's.
When actually integrating it, I felt that you need to prepare test data close to your use case and decide which threshold to use.