I Showed a Document Image (in English) to OpenAI's Decisions API and Had It Find Errors in the OCR Results

This page has been translated by machine translation. View original
Hello, I'm Keima.
When extracting values from documents with a VLM, even if you ask the VLM itself "Is this value correct?", it sometimes returns high confidence for a misread value.
In I showed Cloudflare's Clef an English document image and had it find OCR errors | DevelopersIO, I passed a document image and the extraction results to Cloudflare's Clef and had it judge "Is this value as shown in the image?", and it detected all 36 planted errors.
OpenAI's Decisions API (model: gpt-6-luna) can also accept an image as input and return the probability of yes for a question.
So this time, I passed the same three English documents and the same questions used in the Clef verification to the Decisions API, and compared the number of detected errors and the tendency of false positives with Clef.
1. Verification conditions
I used the same data as the Clef verification.
I injected three patterns of errors (12 each, 36 in total) into the results of extracting an English quote, invoice, and receipt (3 documents, 91 fields in total) with Claude Haiku 4.5.
-
Digit change (12): change just one digit of an amount or date (
$1,150.00→$1,160.00,09/18/2026→09/19/2026) -
Change to similar characters (12): replace with characters easily confused in OCR (
0→O,1→l,m→rn) -
Replacement with another value (12): replace with another word that is not unnatural in context (
SAMPLE MART→FRESH MARKET,Service→Hardware)
The judgment method is also the same as in the Clef verification.
I pass one document image and the extraction results, and for each field ask with a predicate (a question that returns the probability of yes) whether "this value is exactly as printed in the image."
A probability below 0.5 is judged as an "error," and the comparison targets were clef and clef-flash (measured values from October 4, 2026).
The request to the Decisions API looks like this (only one question is excerpted).
The comments are for explanation and are not included in the JSON actually sent.
{
  "model": "gpt-6-luna",
  "input": [{
    "role": "user",
    "content": [
      // Premise for the judgment (an OCR system read the invoice image and extracted keys and values; verify against the image) and the extraction results
      {"type": "input_text", "text": "{\"task\": \"An OCR system read the attached invoice image and produced these key-value pairs. Verify them against the image.\", \"extracted\": {\"invoice_no\": \"INV-2026-0042\", ...}}"},
      {"type": "input_image", "image_url": "data:image/png;base64,..."}
    ]
  }],
  "questions": [{
    "type": "predicate", // A yes/no question. Returns the probability of yes
    "name": "field__invoice_no",
    // Does the extracted value of invoice_no match the string printed in the document image exactly, character for character?
    "instructions": "Is the extracted value of \"invoice_no\" (\"INV-2026-0042\") exactly what is printed in the document image, character for character?"
  }]
}
Clef's noul corresponds to predicate in the Decisions API.
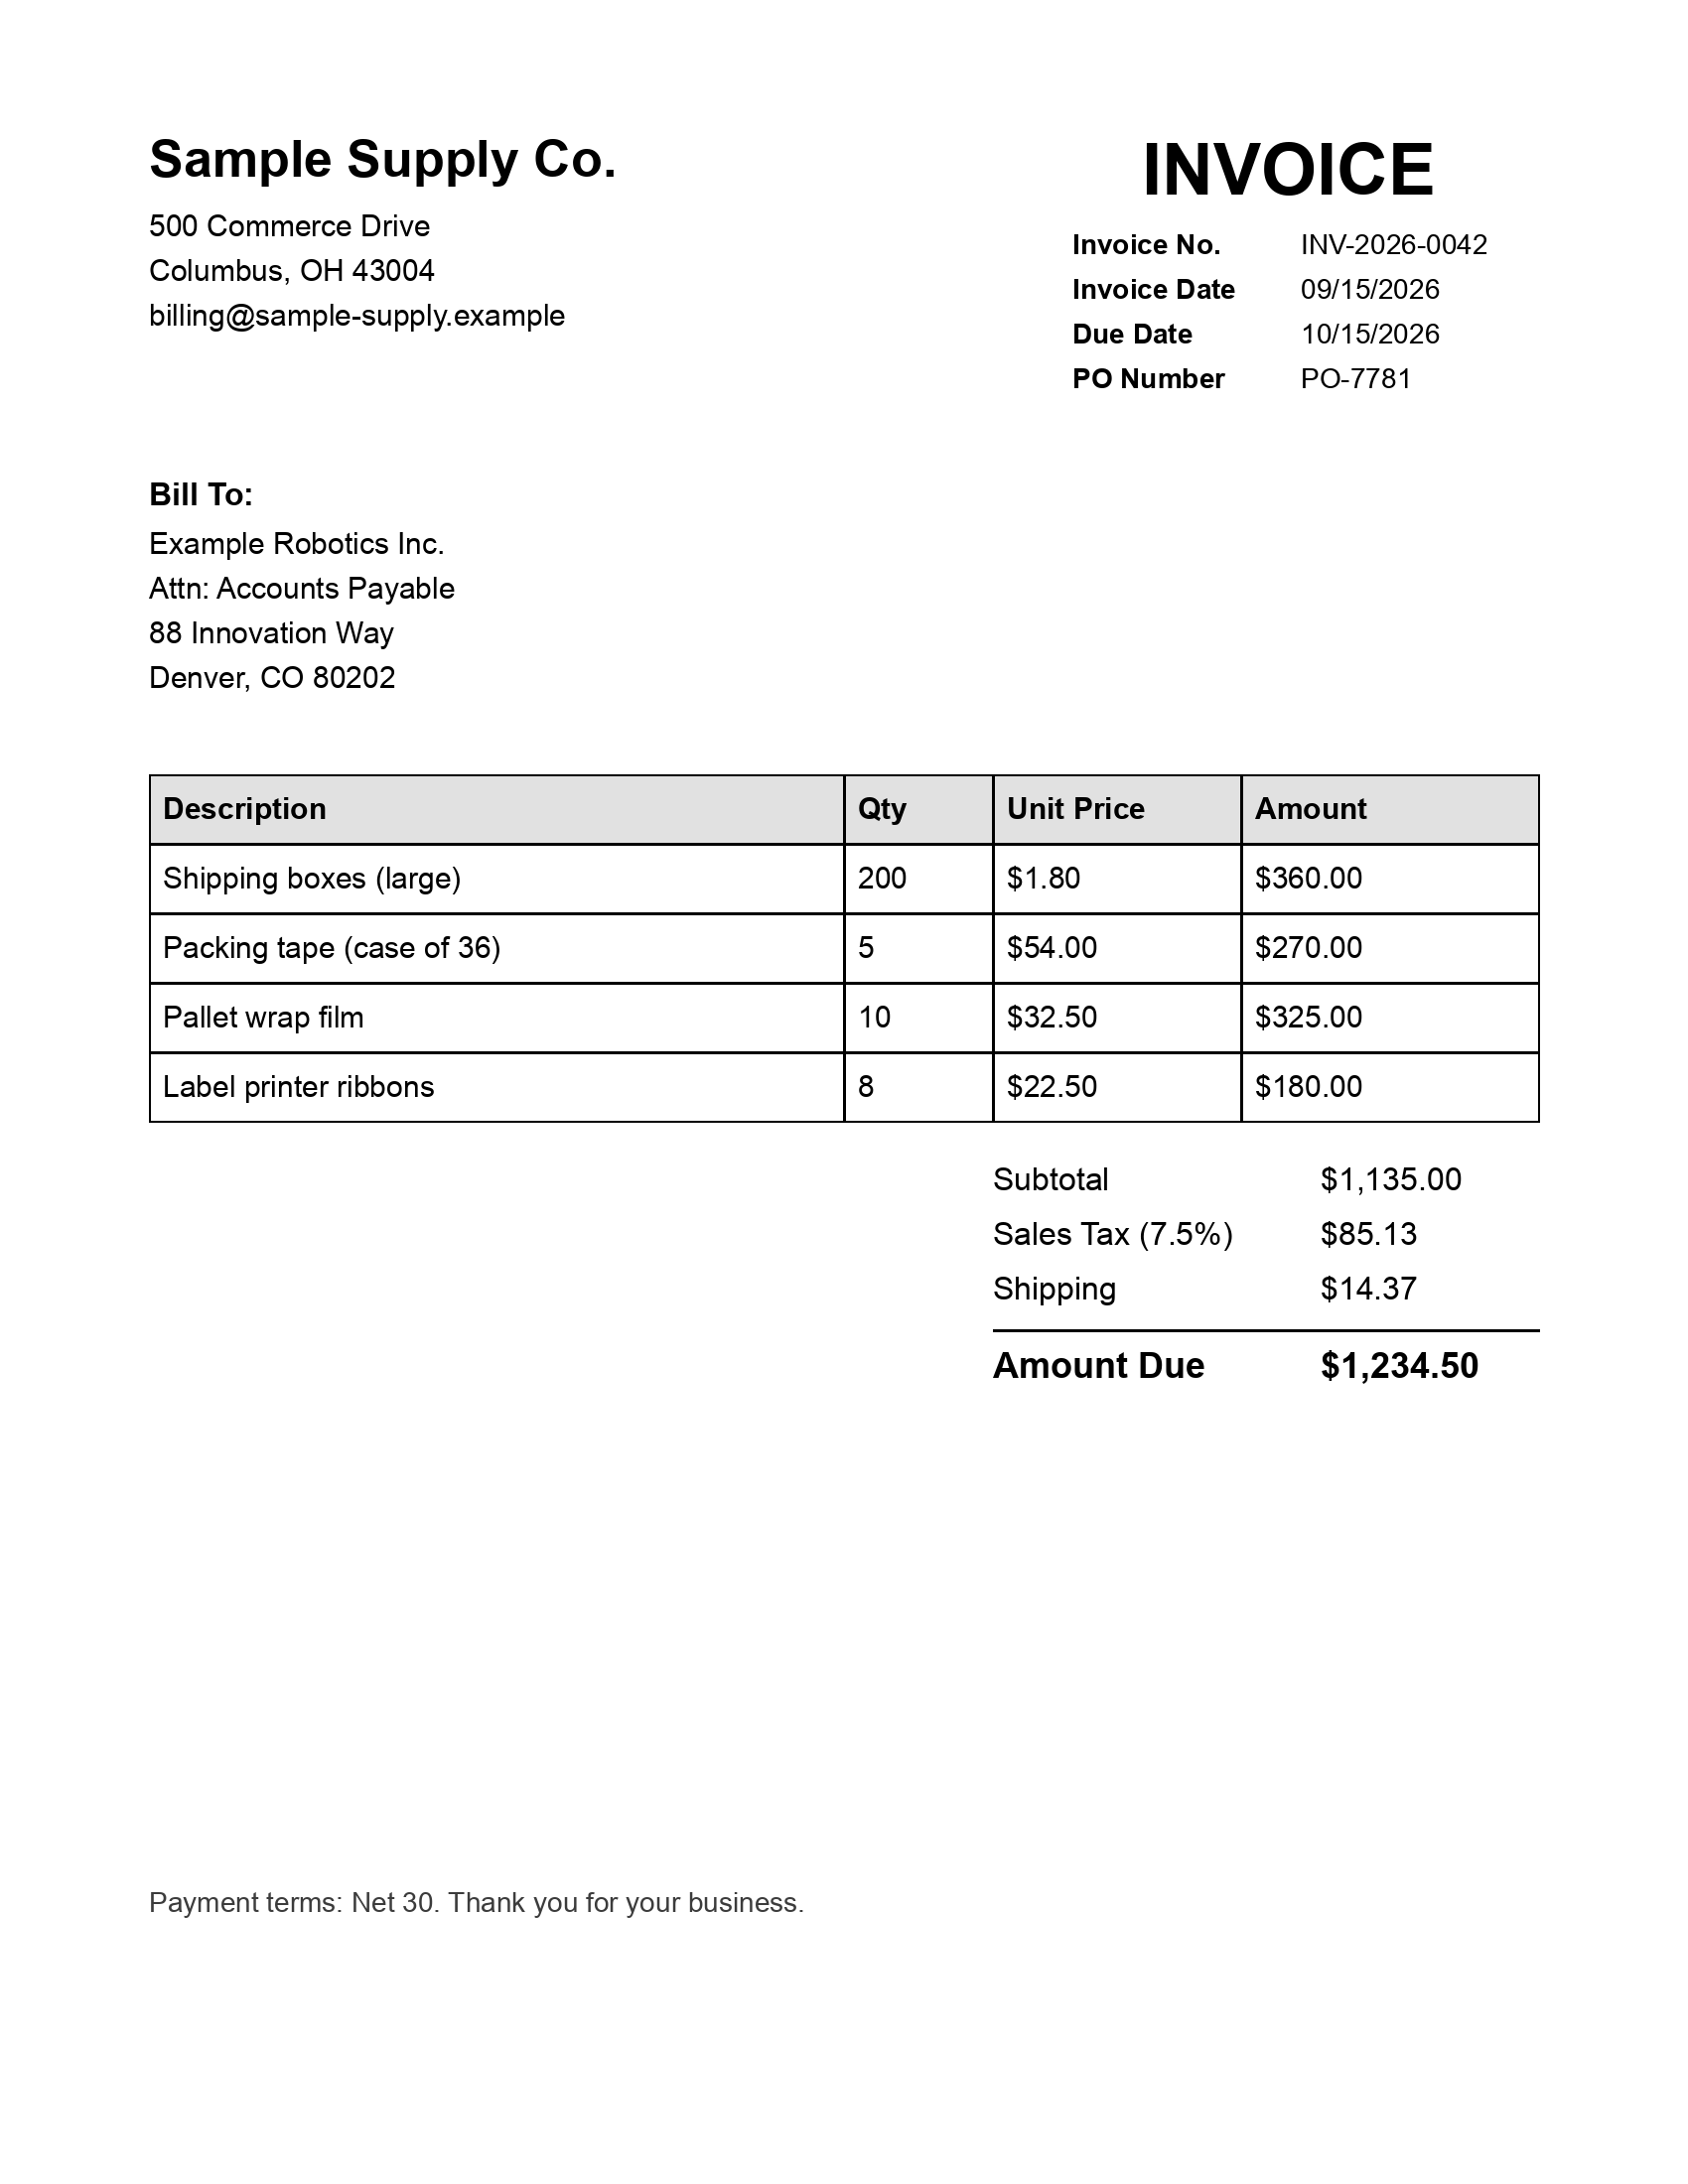
The invoice used in the verification
2. Results
2.1 Could it find the errors?
Each model returns, for each field, the "probability that the value matches the image."
Fields whose probability was below 0.5 were judged as "errors," and I counted them from the following two perspectives.
-
Error detection: the number of the 36 injected errors that were correctly judged as "errors"
-
False positives: the number of values that were actually correct but were judged as "errors"
| Condition | Error detection (out of 36) | False positives (out of 237) |
|---|---|---|
| Decisions API | 36 | 5 |
| clef | 36 | 0 |
| clef-flash | 36 | 3 |
The Decisions API also detected all 36 injected errors.
On the other hand, there were 5 false positives where correct values were judged as errors, which is more than clef (0) and clef-flash (3).
| Document | Version | Field | Extracted value (correct, as in the image) | Decisions API probability |
|---|---|---|---|---|
| Invoice | No errors | bill_to_attn |
Accounts Payable |
0.35 |
| Invoice | B | bill_to_attn |
Accounts Payable |
0.07 |
| Quote | A | item4_category |
Software |
0.46 |
| Quote | A | tax_rate |
8% |
0.47 |
| Quote | A | note |
Prices are valid for 30 days from the quote date. |
0.36 |
The bill_to_attn on the invoice is printed as "Attn: Accounts Payable" in the image.
Since the extracted value did not include "Attn:", the Decisions API seems to have interpreted the instruction "exactly matches character for character" strictly and judged it as a mismatch.
The match probabilities for the 36 injected errors are as follows.
The lower the value, the more strongly the model judges that it "does not match the image."
Match probabilities for the 36 injected errors (click to expand)
| Document | Version | Field | Correct value | Injected value | Pattern | Decisions API | clef | clef-flash |
|---|---|---|---|---|---|---|---|---|
| Quote | A | item1_unit_price |
$1,150.00 |
$1,160.00 |
Digit | 0.00 | 0.02 | 0.02 |
| Quote | A | tax |
$431.12 |
$431.72 |
Digit | 0.00 | 0.23 | 0.05 |
| Quote | A | quote_no |
Q-2026-0187 |
Q-2026-O187 |
Similar char | 0.05 | 0.06 | 0.10 |
| Quote | A | item3_amount |
$435.00 |
$435.0O |
Similar char | 0.00 | 0.02 | 0.16 |
| Quote | A | item4_name |
Office suite license |
Project management tool |
Replacement | 0.00 | 0.02 | 0.02 |
| Quote | A | item6_category |
Service |
Hardware |
Replacement | 0.00 | 0.01 | 0.03 |
| Quote | B | date |
09/18/2026 |
09/19/2026 |
Digit | 0.00 | 0.02 | 0.03 |
| Quote | B | item3_qty |
3 |
5 |
Digit | 0.00 | 0.03 | 0.02 |
| Quote | B | total |
$5,820.12 |
$5,82O.12 |
Similar char | 0.00 | 0.07 | 0.10 |
| Quote | B | item1_name |
Laptop computer |
Laptop cornputer |
Similar char | 0.00 | 0.03 | 0.08 |
| Quote | B | item2_amount |
$840.00 |
$1,240.00 |
Replacement | 0.00 | 0.03 | 0.11 |
| Quote | B | note |
Prices are valid for 30 days from the quote date. |
Prices include free shipping. |
Replacement | 0.00 | 0.02 | 0.02 |
| Invoice | A | invoice_no |
INV-2026-0042 |
INV-2026-0045 |
Digit | 0.00 | 0.02 | 0.02 |
| Invoice | A | item2_qty |
5 |
6 |
Digit | 0.00 | 0.06 | 0.03 |
| Invoice | A | vendor_address_line2 |
Columbus, OH 43004 |
Columbus, OH 43OO4 |
Similar char | 0.01 | 0.05 | 0.04 |
| Invoice | A | bill_to_address_line1 |
88 Innovation Way |
B8 Innovation Way |
Similar char | 0.00 | 0.13 | 0.04 |
| Invoice | A | bill_to_name |
Example Robotics Inc. |
Example Logistics LLC |
Replacement | 0.00 | 0.03 | 0.02 |
| Invoice | A | payment_terms |
Net 30 |
Due on receipt |
Replacement | 0.00 | 0.02 | 0.02 |
| Invoice | B | due_date |
10/15/2026 |
10/16/2026 |
Digit | 0.00 | 0.08 | 0.02 |
| Invoice | B | amount_due |
$1,234.50 |
$1,284.50 |
Digit | 0.00 | 0.07 | 0.04 |
| Invoice | B | po_number |
PO-7781 |
PO-778l |
Similar char | 0.00 | 0.07 | 0.08 |
| Invoice | B | vendor_email |
billing@sample-supply.example |
billing@sarnple-supply.example |
Similar char | 0.00 | 0.03 | 0.03 |
| Invoice | B | item3_description |
Pallet wrap film |
Bubble wrap roll |
Replacement | 0.00 | 0.03 | 0.02 |
| Invoice | B | shipping |
$14.37 |
$0.00 |
Replacement | 0.00 | 0.02 | 0.02 |
| Receipt | A | item2_price |
3.49 |
3.48 |
Digit | 0.00 | 0.11 | 0.02 |
| Receipt | A | time |
14:32 |
14:52 |
Digit | 0.00 | 0.04 | 0.01 |
| Receipt | A | receipt_no |
#0815 |
#O815 |
Similar char | 0.08 | 0.07 | 0.13 |
| Receipt | A | total |
28.94 |
2B.94 |
Similar char | 0.00 | 0.04 | 0.01 |
| Receipt | A | item4_name |
APPLES 2LB |
BANANAS 3LB |
Replacement | 0.00 | 0.03 | 0.01 |
| Receipt | A | store_name |
SAMPLE MART |
FRESH MARKET |
Replacement | 0.00 | 0.02 | 0.01 |
| Receipt | B | date |
09/21/2026 |
09/27/2026 |
Digit | 0.00 | 0.03 | 0.01 |
| Receipt | B | item5_price |
11.99 |
17.99 |
Digit | 0.00 | 0.03 | 0.01 |
| Receipt | B | store_address_line2 |
Portland, OR 97201 |
Portland, OR 972O1 |
Similar char | 0.02 | 0.06 | 0.05 |
| Receipt | B | payment_card |
VISA ****0000 |
VISA ****OOOO |
Similar char | 0.02 | 0.09 | 0.12 |
| Receipt | B | item1_name |
MILK 1GAL |
ORANGE JUICE |
Replacement | 0.00 | 0.02 | 0.01 |
| Receipt | B | subtotal |
28.94 |
31.50 |
Replacement | 0.00 | 0.03 | 0.01 |
2.2 How the probabilities separate
The spread of the probabilities output for the erroneous fields (36) and the correct fields (237) is as follows.
The bottom 5% and top 5% are the values at the lowest 5% and 95% when the probabilities are sorted in ascending order.
| Condition | Target | Min | Bottom 5% | Median | Top 5% | Max |
|---|---|---|---|---|---|---|
| Decisions API | Errors | 0.0 | 0.0 | 0.0 | 0.028 | 0.08 |
| Decisions API | Correct values | 0.07 | 0.718 | 1.0 | 1.0 | 1.0 |
| clef | Errors | 0.012 | 0.016 | 0.030 | 0.112 | 0.227 |
| clef | Correct values | 0.622 | 0.769 | 0.914 | 0.974 | 0.983 |
| clef-flash | Errors | 0.009 | 0.012 | 0.023 | 0.122 | 0.162 |
| clef-flash | Correct values | 0.166 | 0.645 | 0.940 | 0.973 | 0.981 |
Treating each field as one point, plotting them per model gives the following.
Note that the following three charts were created by Claude based on the verification result data.
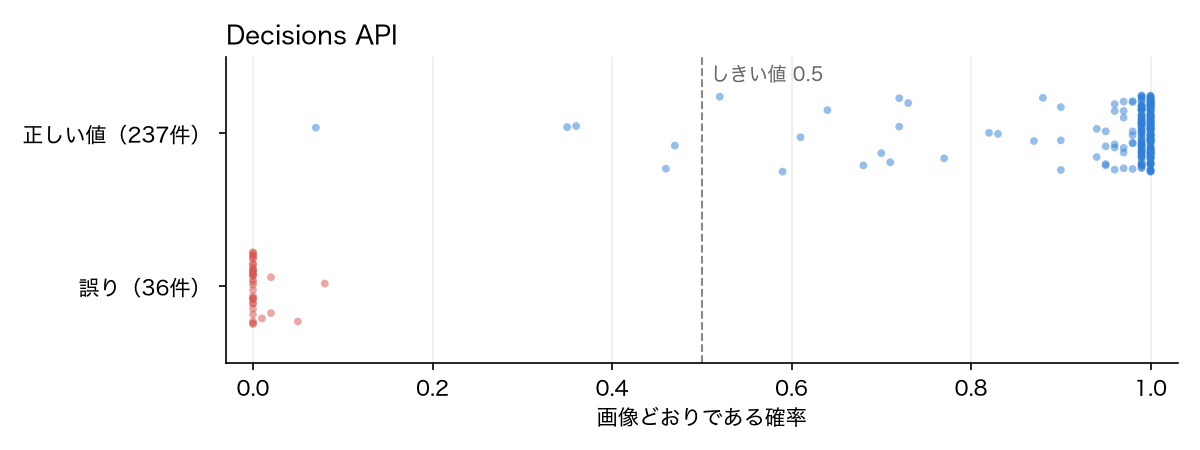
Decisions API: errors cluster around 0.0, and correct values cluster around 1.0
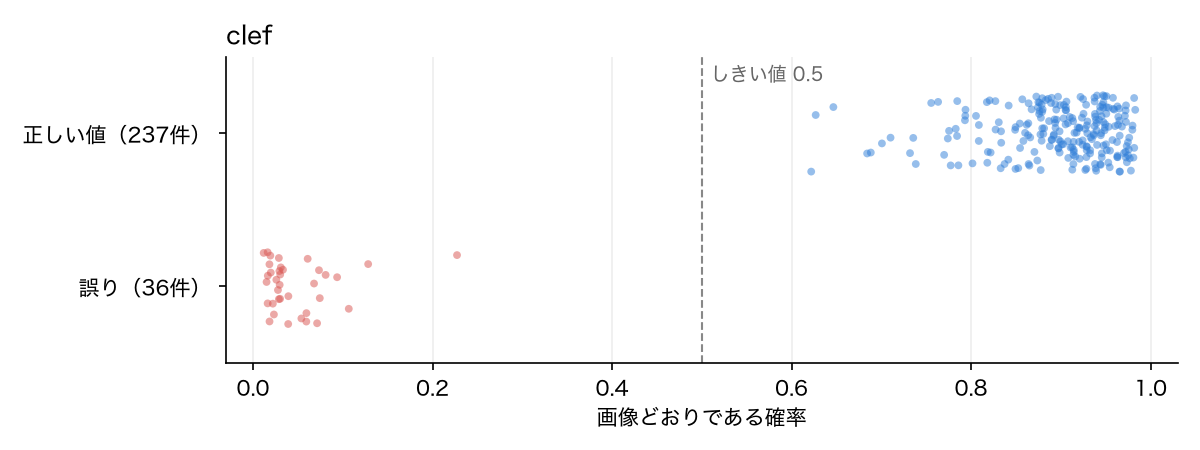
clef: errors are scattered in the 0.0–0.2 range, and correct values in the 0.6–0.9 range
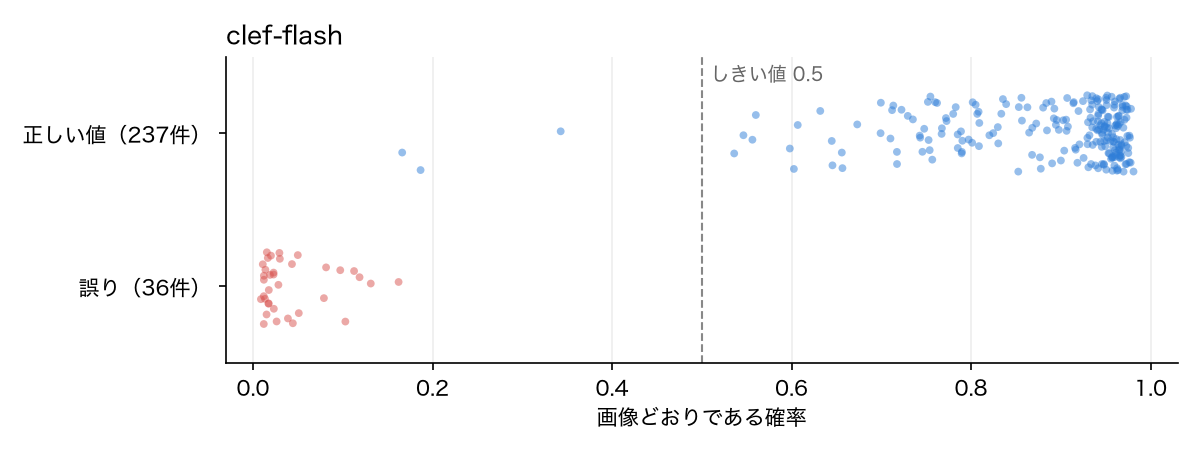
clef-flash: the separation is close to clef, but some correct values fall below 0.5
The probabilities output by the Decisions API were heavily skewed toward the extremes.
Of the 36 errors, 31 were exactly 0.0, and of the 237 correct values, 123 were exactly 1.0, so it did not show the gradual spread into the 0.9 and 0.0 ranges seen with Clef.
On the other hand, the bottom 5% of correct values was 0.718, so some low values comparable to Clef also appeared.
The results when changing the threshold are as follows.
| Threshold | Decisions API: detected | Decisions API: false positives | clef: detected | clef: false positives | clef-flash: detected | clef-flash: false positives |
|---|---|---|---|---|---|---|
| 0.1 | 36/36 | 1/237 | 33/36 | 0/237 | 31/36 | 0/237 |
| 0.3 | 36/36 | 1/237 | 36/36 | 0/237 | 36/36 | 2/237 |
| 0.5 | 36/36 | 5/237 | 36/36 | 0/237 | 36/36 | 3/237 |
| 0.7 | 36/36 | 10/237 | 36/36 | 5/237 | 36/36 | 18/237 |
| 0.8 | 36/36 | 16/237 | 36/36 | 23/237 | 36/36 | 50/237 |
Since all the Decisions API's probabilities for errors were 0.08 or below, it could detect all 36 even when the threshold was lowered to 0.1.
2.3 Time and cost
I made one request per document, sending one image together with the questions for all fields in that document (21 to 38 questions).
The time is the measured value when calling the REST API from within Japan, and the cost is calculated at 150 yen per dollar.
| Condition | Time per request (median) | Total time for 9 requests | Input tokens per request | Total cost for 9 requests |
|---|---|---|---|---|
| Decisions API | 0.638 s (638 ms) | 7.02 s | About 10,160 | $0.0078 (about 1.16 yen) |
| clef | 1.737 s (1,737 ms) | 14.46 s | About 5,280 | $0.0103 (about 1.55 yen) |
| clef-flash | 0.953 s (953 ms) | 8.69 s | About 5,280 | $0.0039 (about 0.58 yen) |
The Decisions API had the fastest response among the three models tested, finishing in about one third of the time of clef.
The number of input tokens increased to about 1.9 times even with the same content as Clef, but because the per-token price is cheaper than clef ($0.24), the total cost came to about three quarters of clef's.
3. Summary
It looks like the Decisions API can take English document images as they are and check whether the OCR extraction results are correct.
However, the tendency for the output probabilities to stick to extremes near 0.0 and 1.0 is a bit of a concern for operation.