Trying Out Grok 4.5 in Grok Build CLI — Comparing Its Responses with Opus 4.8, Sonnet 5, and GPT-5.5

This page has been translated by machine translation. View original
Introduction
On July 8, 2026, xAI released Grok 4.5.
According to xAI's official announcement (x.ai/news/grok-4-5), it ranks first among the listed models on SWE Marathon (29.0%) and achieves 83.3% on Terminal Bench 2.1. API pricing is $2 input / $6 output (both per 1 million tokens), and the average number of output tokens on SWE Bench Pro tasks is said to be about 1/4.2 of Opus 4.8 (max).
Grok Build CLI is officially called a "coding agent," but it can also be used in a general-purpose way to get responses to arbitrary prompts. This time I used an account subscribed to X Premium+ and authenticated via the browser with grok login.
Verification
Installing Grok Build CLI and headless execution
The test environment is as follows.
| Item | Value |
|---|---|
| OS | Fedora Linux 44 (Asahi Remix) |
| Architecture | aarch64 (Apple Silicon) |
| Grok Build CLI | v0.2.93 (stable) |
| Kiro CLI | v2.12.0 |
| Codex CLI | v0.144.1 |
Installation
You can install it with a one-liner.
curl -fsSL https://x.ai/cli/install.sh | bash
$ grok --version
grok 0.2.93 (f00f96316d) [stable]
The binary is placed at ~/.grok/bin/grok.
Authentication
On first launch, a browser opens and you sign in with your X account. The authentication method is OIDC, and the issuer is https://auth.x.ai.
After authentication completes, the token is cached in ~/.grok/auth.json. From then on, you can run the CLI without opening a browser, and no API key setup is required.
X Premium+ settings
The X account used for verification is subscribed to Premium+.
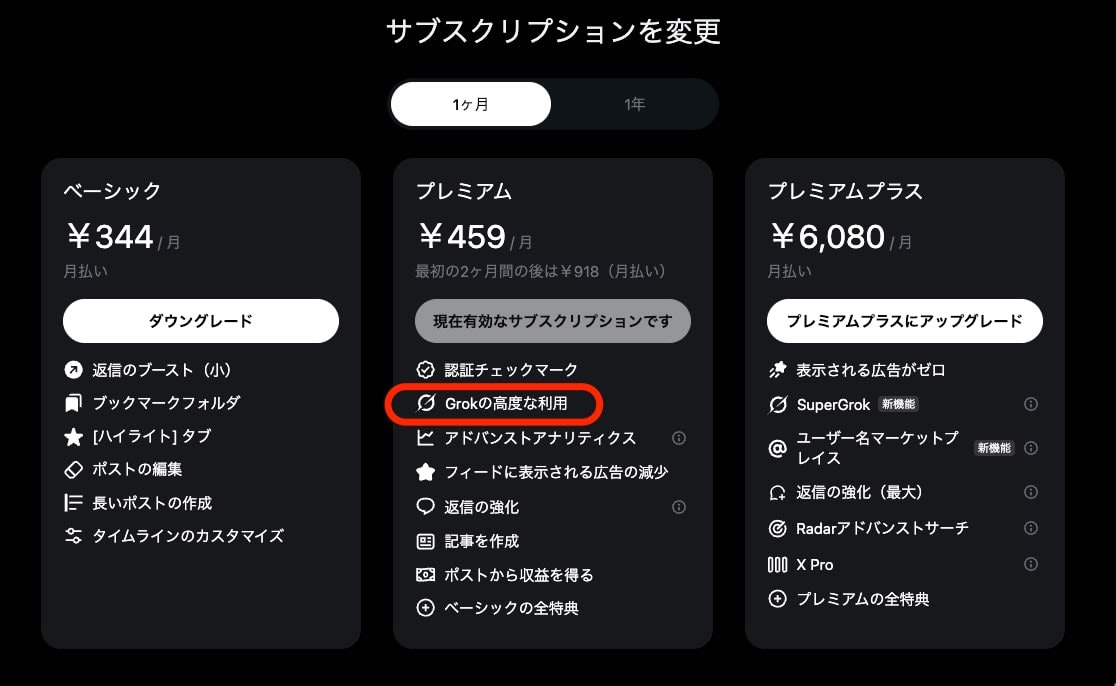
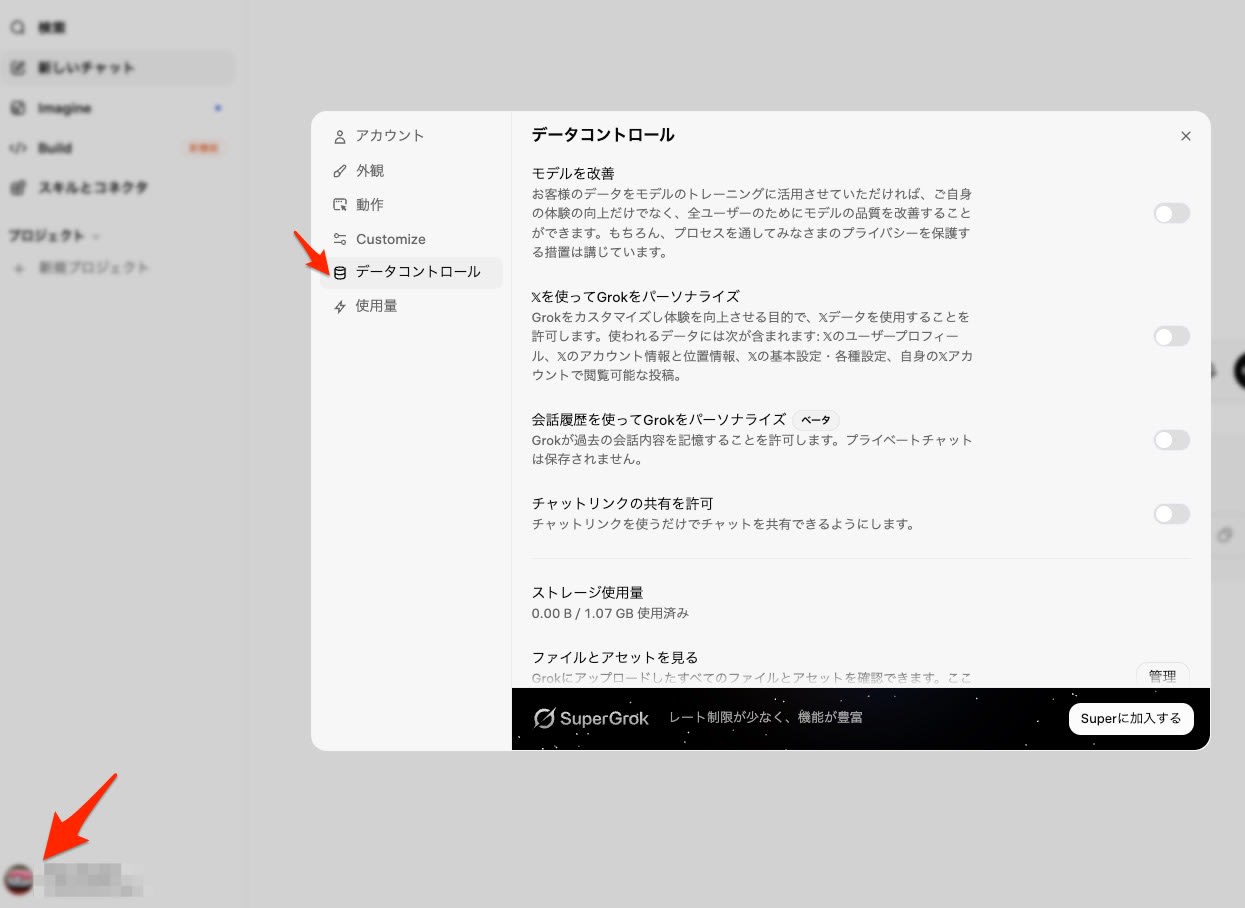
In Grok's data controls settings, I opted out of data use for training. On the CLI side as well, I manually set coding_data_retention_opt_out: true in ~/.grok/auth.json.
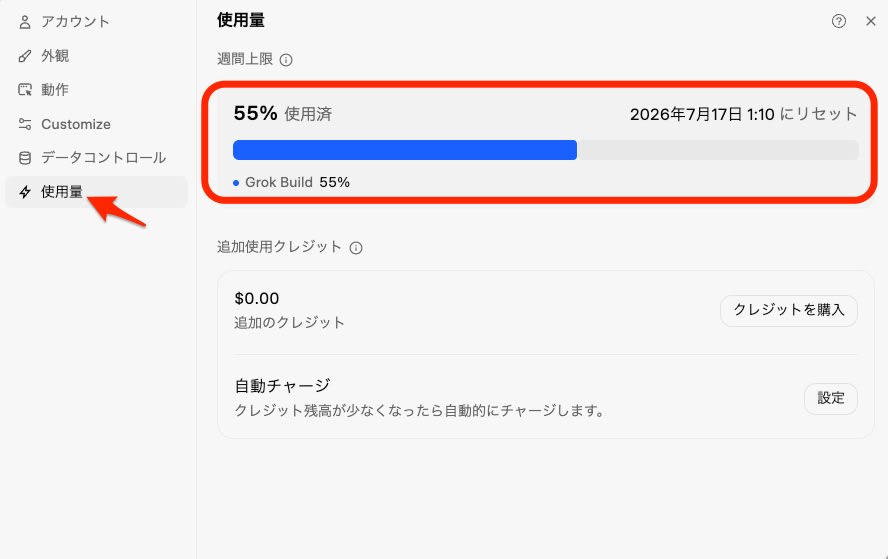
Grok usage resets weekly and is displayed as a percentage. The specific number of credits is not disclosed. Before and after running the three prompt comparisons, the weekly usage included in the subscription went from 55% to 57%.
Headless mode
With the -p (--single) option, the CLI returns the result to standard output after a single prompt execution, without opening an interactive session.
grok -p "Explain this codebase" --output-format plain --effort medium
Main options:
| Option | Description |
|---|---|
-p / --single |
Headless mode (single prompt execution) |
--prompt-file |
Read the prompt from a file |
--output-format |
Output format (plain / json / streaming-json) |
-m / --model |
Model selection (at time of verification: grok-4.5 500K / grok-composer-2.5-fast 200K) |
--effort |
Reasoning depth (high / medium / low) |
Prompt comparison: Generating an AWS architecture diagram (DrawIO XML)
I gave the same prompt to four agents and had them generate XML in DrawIO format. Note that the reasoning settings available differ for each CLI (Grok: --effort medium, Kiro: --effort xhigh). In this article, I compare the outputs with the settings as specified at execution time.
Prompt
Please create an AWS architecture diagram as DrawIO-format XML with the following requirements. Use AWS simple icons (AWS 2024 shape library).
Requirements:
- Deliver content to users via CloudFront
- VPC with a multi-AZ configuration (2 AZs)
- Load balancing with ALB (Application Load Balancer)
- One EC2 instance in each AZ (2 in total)
- RDS in a multi-AZ deployment (primary + standby)
- Place each component in an appropriate subnet (Public/Private)
Return only complete XML that can be loaded in DrawIO. No explanation is needed.
Results
All four agents output XML. The outputs of Grok 4.5, Opus 4.8, and Sonnet 5 could be loaded in DrawIO as-is, while Codex (GPT-5.5) could be loaded after fixing the diagram name.
Below are the results of opening each output in DrawIO.
Grok 4.5
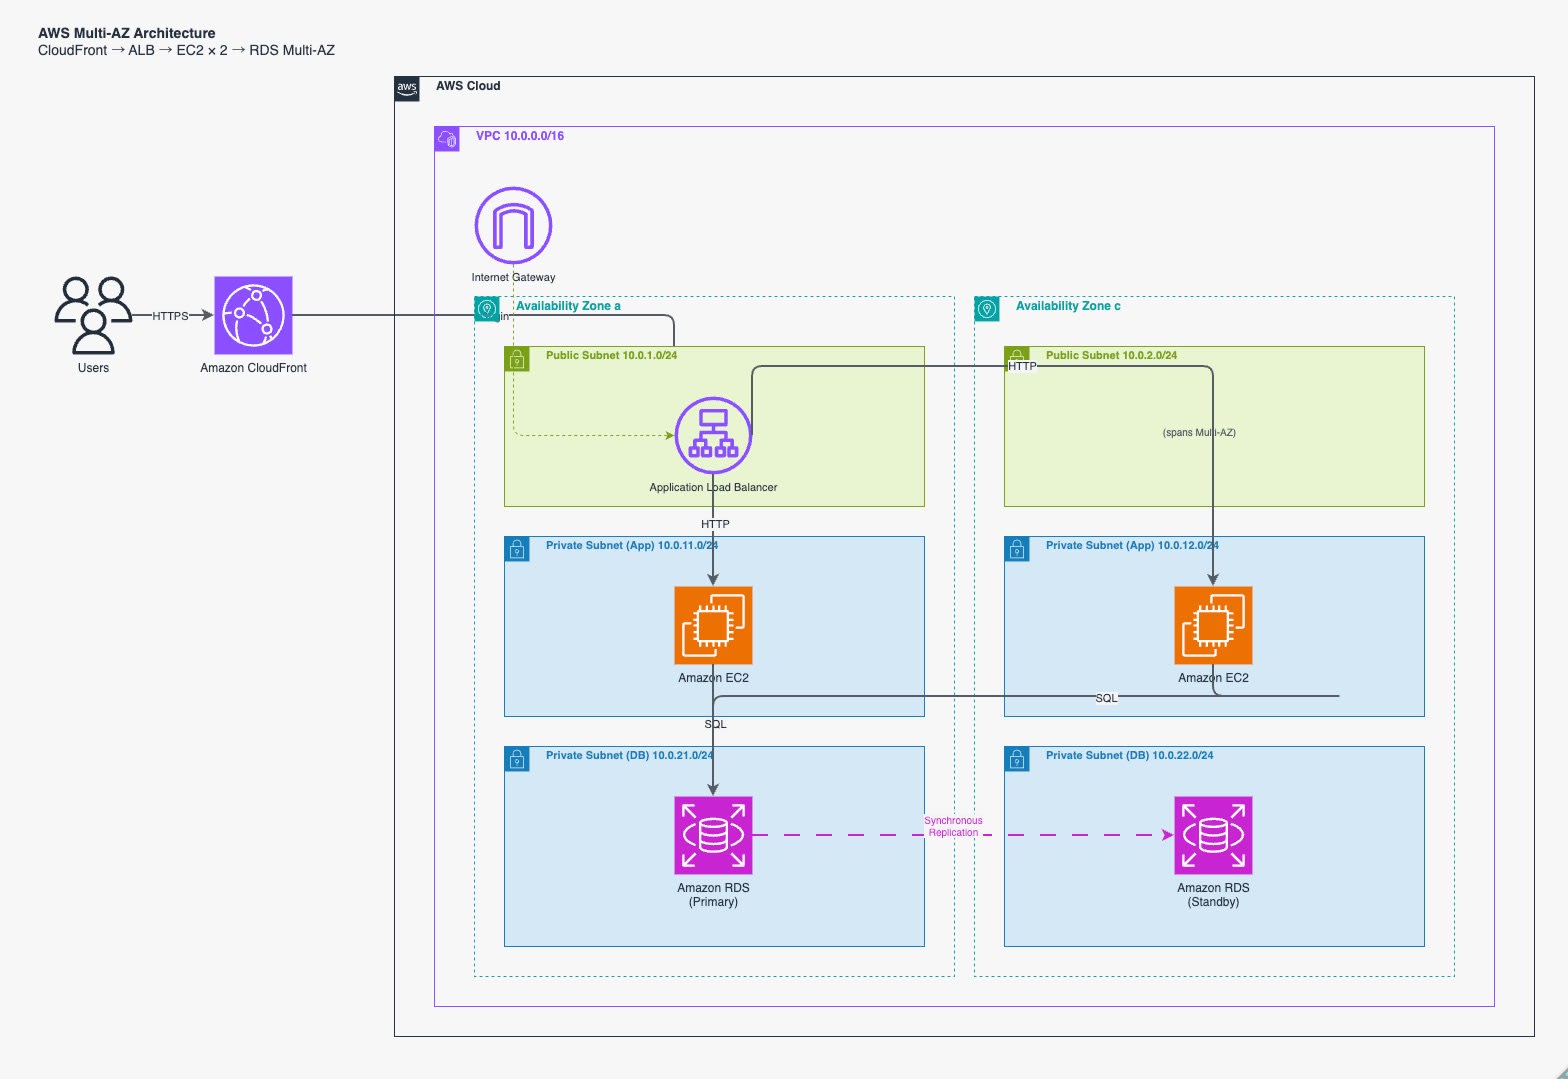
This was the most detailed output. It includes CIDR notation, a three-tier subnet separation (Public/Private/DB), protocol labels (HTTPS/HTTP/SQL), and an arrow for Synchronous Replication.
Kiro — Opus 4.8
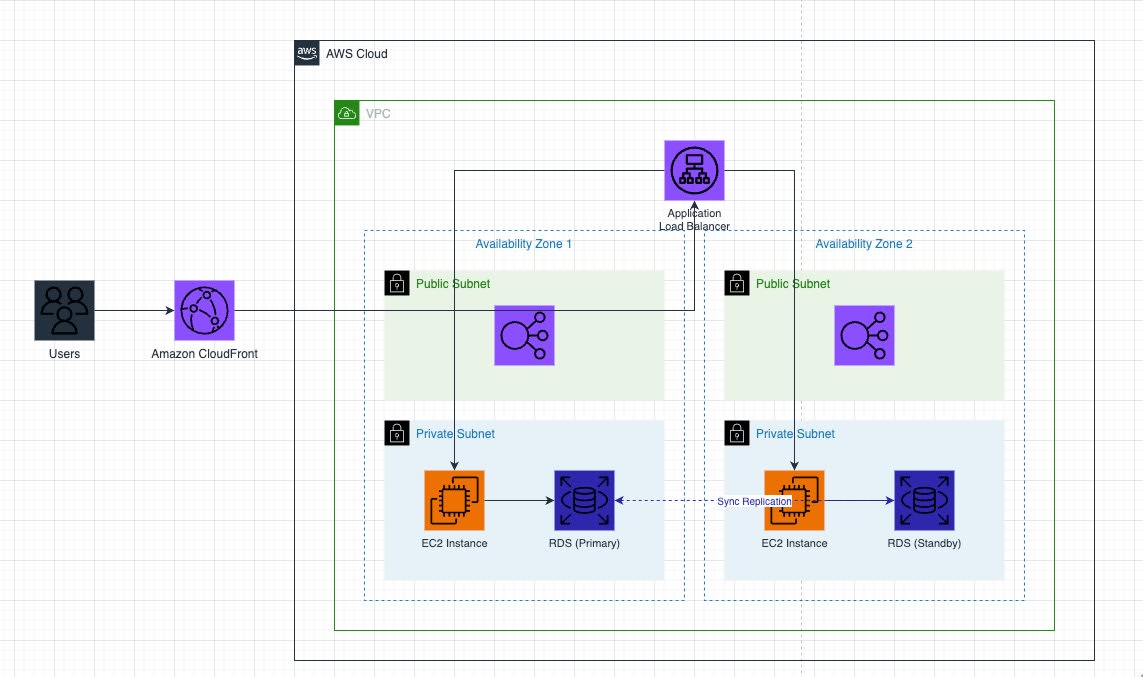
A compact output. It has only two tiers, Public/Private, and EC2 and RDS share the same Private Subnet. The ALB is placed at the top of the VPC, spanning the AZs.
Kiro — Sonnet 5
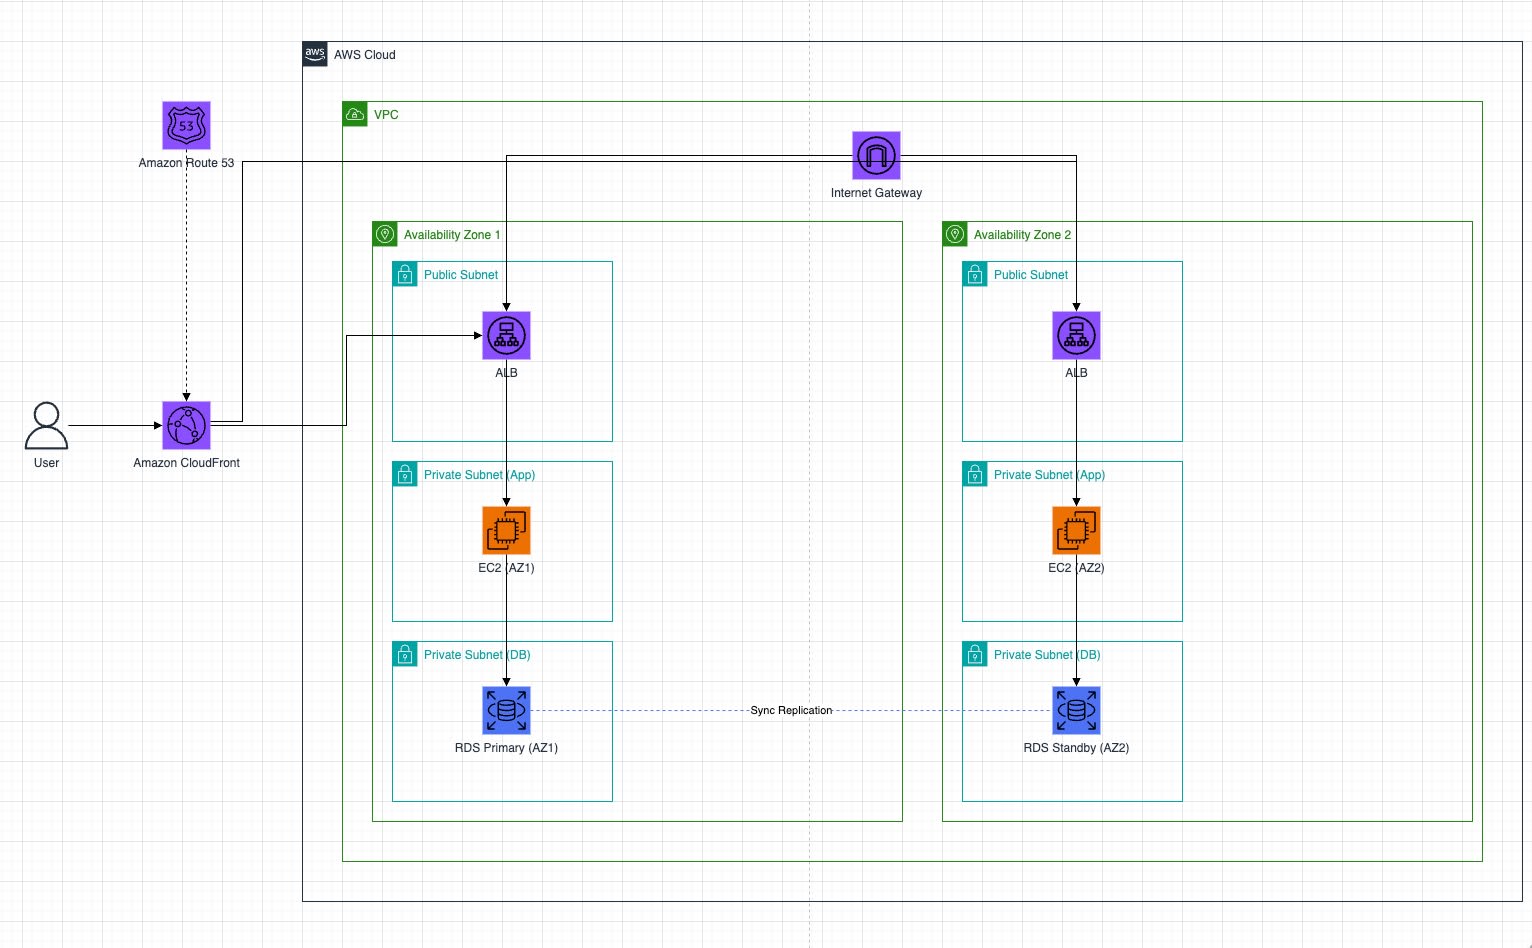
Route 53 has been added (not in the requirements). The Internet Gateway is shown explicitly, and the structure has three tiers: Public/Private(App)/Private(DB). It draws one ALB in each AZ, but an ALB is actually a single resource that spans AZs, so this is somewhat inaccurate as an architectural representation.
Codex — GPT-5.5
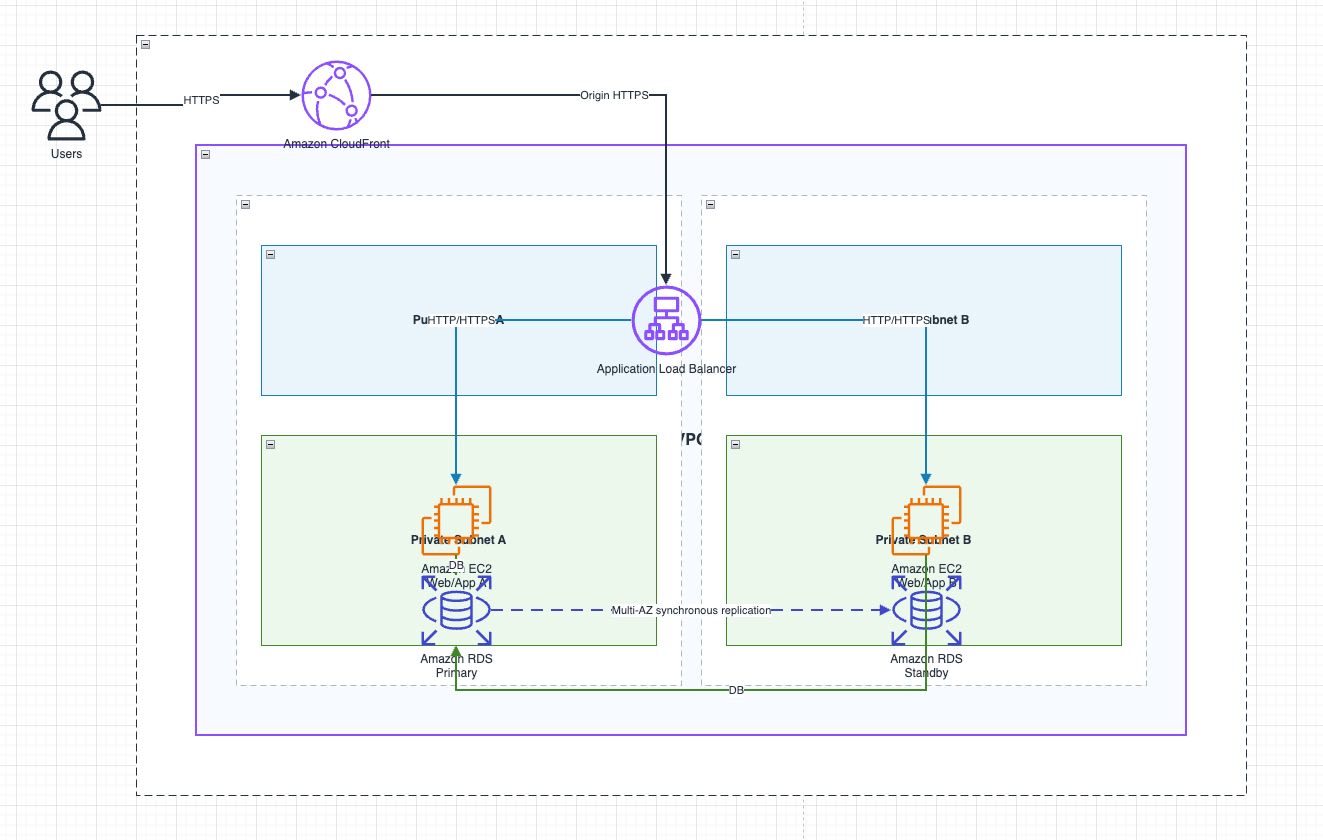
Overlapping labels stand out (coordinate shifts such as "PuHTTP/HTTPSA" and "AmaDB, EC2 Web/App"). The structure is understandable, but the appearance is broken.
Prompt comparison: Organizing specifications from ambiguous requirements
Prompt
A user told me, "We want to complete our internal attendance management entirely in Slack." As a requirements definition, please list five each of the necessary features, technology choices, and anticipated challenges.
Comparison
| Aspect | Grok 4.5 | Opus 4.8 | Sonnet 5 | GPT-5.5 |
|---|---|---|---|---|
| Adherence to "five" | ✅ (5 items each + supplements) | ✅ (5 items each) | ✅ (5 items each) | ✅ (5 items each) |
| Granularity of features | Table format with overviews. Comprehensive from clocking in to export | Bullet points. Includes reminders and compliance notifications | Bullet points. Separates clock in/out, breaks, and temporary absences as distinct features | Bullet points. Concise 5 items |
| Rationale for technology choices | Selection reason alongside each technology (table format) | Reason alongside each technology (prose) | Reason alongside each technology (prose) | One-line reason alongside each technology |
| Specificity of challenges | Goes as far as legal compliance, Article 36 agreements, and location data | Raises legal compliance, fallback during outages, and integrations | Mentions legal evidentiary value, offline measures, and vendor lock-in | Briefly lists proxy clocking, time zones, and vendor risk |
| Volume | Largest (table + supplements) | Medium | Medium | Smallest (concise) |
Full responses from each agent (click to expand)
Grok 4.5's response
Assuming "everything from clocking in through requests, approvals, and aggregation is handled in Slack," I'll organize this as a draft requirements definition.
1. List of necessary features (5)
| # | Feature | Overview |
|---|---|---|
| 1 | Clocking (clock in/out, breaks) | Clock in via Slack buttons / shortcuts / slash commands. Automatic recording of clocking times, detection of late arrivals and early departures, and work style tags such as remote / on-site. |
| 2 | Request workflow for leave, overtime, etc. | Enter requests for paid leave, half-day leave, compensatory leave, overtime, shift swaps, etc. in a modal → approval request to the supervisor → approval/rejection notification. List view of request status. |
| 3 | Approval and reminders | DM / channel notifications to supervisors, reminders for unapproved items, proxy approval, escalation. Notification of approval results to the requester and HR. |
| 4 | Viewing and correcting attendance data | Monthly attendance check by the individual, correction requests for missed clock-ins, correction and finalization by administrators. Daily / monthly summaries (working hours, overtime, remaining paid leave, etc.). |
| 5 | Aggregation, export, and external integration | Monthly closing, CSV / API output for payroll calculation, integration with existing HR, payroll, and accounting systems. Operation logs for auditing. |
Often-needed supplements: holiday calendar, core time / flextime support, Article 36 agreement alerts, location and IP restrictions (countermeasures against fraudulent clocking), multilingual and multi-site support.
2. Technology choices (5)
| # | Area | Recommended candidate | Reason for selection |
|---|---|---|---|
| 1 | Slack integration | Slack Bolt (Node.js / Python) + Socket Mode or HTTP Request URL | The official SDK makes it easy to implement modals, interactivity, and events. Socket Mode is advantageous if internal firewall restrictions apply. |
| 2 | Backend | Node.js (TypeScript) or Python (FastAPI) | Choose based on affinity with Bolt, asynchronous processing, and in-house skill set. |
| 3 | Data store | PostgreSQL (main) + Redis (cache / queue) | Transactions and history are important for attendance. Jobs (closing processes, reminders) should be queued. |
| 4 | Authentication and permissions | Slack OAuth / OpenID Connect + integration with the internal IdP (Okta, Azure AD, etc.) | Link Slack users with the employee master. RBAC based on department and position. |
| 5 | Infrastructure and operations | Containers (ECS / Cloud Run / k8s) + managed DB + monitoring (CloudWatch / Datadog, etc.) | Ensures availability, audit logs, and backups. Run nightly batches and monthly closing with a scheduler. |
3. Anticipated challenges (5)
| # | Challenge | Details and direction for countermeasures |
|---|---|---|
| 1 | Legal and labor compliance | Conformance with the Labor Standards Act (objective recording of clocking, overtime limits, paid leave management). Specify rounding rules and the handling of late-night and holiday work in the specifications, and review them with HR/labor staff. |
| 2 | Fraudulent clocking and impersonation | Clocking on behalf of others, spoofing via VPN, etc. Deter with IP restrictions, device / location options, tamper prevention for clocking logs, and administrator audits. |
| 3 | Dependence on Slack outages and missed notifications | If clocking is impossible when Slack is down, work stops. Consider web / mobile fallbacks, after-the-fact synchronization of offline clocking, and using email for important notifications. |
| 4 | Complexity of organization master and permissions | Concurrent positions, proxy approval, reorganizations, secondments. Synchronization design with the HR master, immediate reflection of permission changes, and history management tend to become bottlenecks. |
| 5 | Double management with existing systems | Data inconsistencies with payroll, HR, and existing attendance systems. Decide the source of truth for the master and clarify the sync direction and rules for post-closing corrections. |
Kiro (Opus 4.8)'s response
I've organized the requirements definition for completing internal attendance management in Slack.
List of necessary features (5)
- Clocking feature (clock in/out, breaks) — Clock in via slash commands (e.g.,
/punch in), shortcuts, or messages with buttons. Includes reminder notifications to prevent forgetting to clock. - Attendance lookup and correction requests — Individuals can check their working hours for the day / month and request corrections for clocking mistakes. It is desirable to include an approval flow for corrections.
- Approval workflow (overtime, leave, corrections) — Requests and approvals to supervisors are completed entirely with interactive messages in Slack (approve / reject buttons). Approval results are automatically notified to the requester.
- Aggregation and report output — Automatically aggregate monthly working hours, overtime hours, and leave days taken, and export CSV / spreadsheets for administrators. Integration with payroll systems is also envisioned.
- Alerts and compliance notifications — Detect long working hours (approaching the Article 36 agreement limit), missed breaks, missed clock-ins, etc., and automatically notify the individual and administrators.
Technology choices (5)
- Slack app foundation: Bolt (Slack's official SDK) — Bolt for Python or JavaScript. Handles slash commands, shortcuts, Block Kit, and event subscriptions uniformly, with strong official support.
- UI construction: Block Kit + Modals — Build an intuitive clocking / request UI with buttons and input forms (modals). Minimizes screen transitions outside Slack.
- Execution environment: Serverless (AWS Lambda + API Gateway) — Clocking is intermittent and event-driven, so it pairs well with serverless. Achieves both cost efficiency and scalability.
- Data store: RDB (Amazon RDS / DynamoDB) — Since accuracy and aggregation are important for attendance, a relational DB is the first candidate. For audit log use, consider an append-only table design.
- Authentication and user integration: Slack user ID × employee master — Link Slack OAuth / user IDs with the employee ledger. For companies with SSO integration, match against the IdP to ensure identity.
Anticipated challenges (5)
- Legal and labor compliance — Under the Labor Standards Act, attendance records must be "objective records." It is essential to confirm with a labor and social security attorney / legal whether Slack clocking is accepted as an objective record.
- Reliability of clocking and fraud prevention — Since Slack can be operated from anywhere, it is hard to guarantee that someone is "actually on-site / working." Coordination with business requirements is needed on how far to require location data, IP restrictions, and impersonation countermeasures.
- Dependence on Slack outages and API rate limits — If Slack goes down, clocking becomes impossible. Fallback measures and design responses to rate limits and the 3-second response limit are required.
- Data consistency and correction operations — Exception handling for missed clock-ins, duplicate clock-ins, time zone differences, etc. Correction history must be kept in an auditable form.
- Integration with existing systems and migration — Integration specifications with payroll and HR systems, migration from existing attendance systems, and handling of the dual-operation period.
Kiro (Sonnet 5)'s response
Here is a draft requirements definition for a system that completes attendance management in Slack.
List of necessary features (5)
- Clock in/out feature — Clock in via slash commands (
/clockin,/clockout) or shortcut buttons. Clocking times also account for UTC/JST conversion - Break and temporary absence management — Records of break start/end and personal outings. Supports multiple temporary absences
- Attendance history and summary view — A command for individuals to check their own monthly attendance in Slack
- Request and approval workflow — Submit leave requests, overtime requests, clocking correction requests, etc. in Slack, and supervisors approve with button actions
- Reminder and alert notifications — Notifications for forgotten clock-ins, and automatic notifications to the individual and supervisor when overtime exceeds a threshold
Technology choices (5)
- Slack Bolt (Node.js/Python) — Slack's official SDK. Handles the Events API, Slash Commands, and Interactivity in an integrated way
- AWS Lambda + API Gateway — Process events from Slack serverlessly. Cost-efficient given the clocking frequency
- DynamoDB or Aurora Serverless — Clocking mostly involves simple key-value access, so DynamoDB; if aggregation is the priority, an RDBMS
- EventBridge Scheduler — Scheduling periodic reminders (forgotten-clock-in checks, monthly closing processing)
- API integration layer with existing attendance and payroll systems — An adapter layer for integration with freee HR, SmartHR, Obic Business Consultants' Bugyo Cloud, etc.
Anticipated challenges (5)
- Ensuring legal clocking accuracy and evidentiary value — Under the Labor Standards Act, attendance records must be objective. Whether Slack button actions alone can prove "clocking by the person themselves" needs examination
- Alternatives during offline or outage situations — If clocking is impossible during Slack or network outages, work stops. An emergency alternative request flow is needed
- Data consistency with existing payroll and HR systems — Data integration with the payroll system is ultimately essential. Risks of format mismatches and time zone shifts
- Fraudulent clocking and impersonation countermeasures — Issues of clocking by proxy via another person's PC or account, and the reliability of clocking without location data
- Dependence on Slack workspace operational risks — A structural risk in which business is directly affected by vendor-side changes such as Slack plan changes, API specification changes, and rate limits
Codex (GPT-5.5)'s response
This is a draft requirements definition assuming internal attendance management is completed in Slack.
List of necessary features
- Clocking feature for clock in/out, breaks, and returns
- Request feature for paid leave, absence, late arrival, early departure, etc.
- Approval and return feature for supervisors
- Attendance status list view and monthly aggregation feature
- Notification feature for missed clock-ins and missed requests
Technology choices
- Slack App / Slack Bolt — To implement commands, buttons, and modals in Slack.
- Backend: Node.js / TypeScript or Python — Used for Slack API integration, attendance logic, and approval flow processing.
- Database: PostgreSQL / MySQL — Manages clocking history, requests, approval status, and user information.
- Hosting: AWS / Google Cloud / Azure — Used for the API server, batch processing, log management, and monitoring.
- Authentication and integration: Slack OAuth / SSO / internal HR system API — To link Slack users with employee information.
Anticipated challenges
- Ensuring clocking accuracy — Proxy clocking, forgotten clock-ins, time zones, and handling during remote work are issues.
- Compliance with labor rules — Compliance with laws and internal regulations such as overtime, paid leave, break time, and Article 36 agreements is required.
- Complexity of approval flows — Needs to handle departments, positions, proxy approval, and multi-stage approval.
- Integration with existing systems — Data synchronization with payroll, HR master, and existing attendance systems is required.
- Security and audit compliance — Management of personal information, attendance logs, change history, permission management, and audit trails is important.
Prompt comparison: Metacognition (observing response style)
Prompt
Please list three strengths and three weaknesses of yours, and honestly state your position compared with other LLMs (Claude, GPT, Grok).
Comparison
The results of this prompt are not used as factual evidence of the models' actual capabilities. They are treated as observations of differences in response style, i.e., how each agent talks about itself.
| Aspect | Grok 4.5 | Opus 4.8 | Sonnet 5 | GPT-5.5 |
|---|---|---|---|---|
| Self-introduction | Explicitly states "xAI's Grok (Grok 4.5)" | Explicitly states "an agent running on claude-opus-4.8" | Explicitly states "using claude-sonnet-5" | Does not state a model name; positions itself as a "practical LLM" |
| How strengths are described | Emphasizes "work you get done hands-on" and "candor" | Emphasizes "execution ability in code implementation and tool integration" and "carefulness" | Emphasizes "development work rooted in the local environment" and "parallel processing" | Emphasizes "codebase investigation and implementation fixes" and "debugging" |
| How weaknesses are admitted | Specific ("tends to become overconfident," "humans are needed for UX") | Specific ("inserts too many confirmations," "weak at numerical calculation") | Declines, saying "not in a position to evaluate objectively" | Frankly admits "vague, sensibility-driven prose expression" |
| Mentions of other models | Compares along axes in a table. Writes fairly | Acknowledges Grok's strength (real-time capability) | Cautious: "avoids it because it would be speculation" | Acknowledges each model's strengths, then defines its own domain |
| Overall tone | Confident and candid. Calls itself a "field engineer" | Calm. Aware of leaning safe; structures strengths and weaknesses | Most cautious. Avoids definitive statements | Practical. Simply defines its own domain |
Grok 4.5 even created a comparison table when mentioning other models, and was the most talkative. It clearly put forward "candor and looser constraints" as its position. Sonnet 5, on the other hand, stood out for avoiding comparisons of superiority with other models, saying it is "not in a position to evaluate objectively."
Full responses from each agent (click to expand)
Grok 4.5's response
Strengths (3)
- Tool-driven practical tasks (implementation, investigation, editing) — Centered on work you "get done hands-on," such as reading and fixing code, running commands, searching the web/X, and editing files. It can easily proceed from design through implementation and verification in one go.
- Broad context and candid explanation — Even in long conversations or large codebases, it can pull out key points and compare and organize them. Even with ambiguous requests, it forms hypotheses and proceeds, stating assumptions explicitly when needed.
- Latest information and multi-source integration — Using web search, X search, etc., it can gather public information and organize it, including conflicting views. From technical topics to current events, it can base answers on "what's happening now."
Weaknesses (3)
- Fully autonomous operation and perfect self-verification — In large designs or long changes, oversights, assumption drift, and insufficient testing can occur. Without human review or an instruction like "verify again," it tends to become overconfident.
- Final judgment in strict specialist domains — In high-responsibility areas such as medicine, law, and accounting, it can provide "reference information" but is no substitute for an expert's final judgment.
- The "authentic feel" of sensory and physical creativity — It can produce text, images, and code, but is weak at final adjustments of sense rooted in human experience, such as on-site tactile feel, sound, atmosphere, and subtle brand tone.
Position compared with other LLMs
| Axis | Claude family | GPT family | Grok (me) |
|---|---|---|---|
| Care in code and long-form text | Strong (readability, carefulness) | Strong (general-purpose, tool ecosystem) | Strong in practical implementation and tool integration, but may fall short of Claude in the "polish" of writing style |
| Candor and looseness of constraints | Cautious, leaning safe | Balanced | Relatively straightforward; on the side designed with weaker censorship |
| Real-time and X integration | Average to weak | Supplemented by plugins, etc. | "Current" information premised on X and search tends to be a strength |
| Deep reasoning and extended thinking | Very strong depending on the model | Reasoning-specialized models like the o series are strong | Capable of practical reasoning, but may lose to dedicated reasoning models on extremely hard problems and competition math |
Rough position: closer to "an engineer who works hands-on alongside you in the field" than to a "best paper award at the research lab."
Kiro (Opus 4.8)'s response
I'll answer honestly. First, as a premise, I (Kiro) am an agent running on the model claude-opus-4.8.
Strengths
- Execution ability in code implementation and tool integration — Rather than merely suggesting code, I actually read and write files, search, run builds/tests, operate AWS, and so on, carrying things through to verification.
- Consistency over long contexts and careful reasoning — Claude-family models are relatively good at giving coherent explanations while retaining long instructions and complex constraints.
- Carefulness and safe-side judgment — Confirming before destructive operations and verifying before concluding—this "resistance to running wild" is a strength in both design and model.
Weaknesses
- Latest information and real-time capability — Training data has a cutoff, so I can't answer about the latest events, prices, or version specifications without searching.
- Exact numerical calculation and large-scale logical search — Calculator-like accuracy and huge combinatorial searches are inherently weak points, and hallucinations creep in.
- Verbosity and excess confirmation from over-carefulness — Because of a design that leans safe, I tend to insert too many confirmations or give lengthy preambles when the user wants me to "just get it done."
Position relative to other LLMs
- Versus the GPT family: On par or ahead in coding and long-form instruction following and safety. The GPT family sometimes leads in general-purpose ecosystem and the lightness of responses for general users.
- Versus the Grok family: Grok has the edge in real-time information and in a casual, uninhibited tone. On the other hand, I'm better suited to solid code, safe operation, and consistency across long contexts.
- Summary: My position is "an agent that goes deep into the development workflow, actually works hands-on, and completes tasks solidly and safely."
Kiro (Sonnet 5)'s response
I'll answer about strengths and weaknesses limited to what I can say from the tools I actually have and my design, not speculation.
Strengths
- Development work rooted in the local environment — File reading/writing, code search (AST-based symbol search), bash command execution, git workflows, and so on are integrated.
- Decomposing complex tasks and parallel processing — I can delegate to sub-agents and process multiple independent subtasks in parallel.
- Safety-conscious execution — There are clear guardrails against destructive operations, and I'm designed to decide whether to ask for confirmation or proceed autonomously depending on the magnitude of risk.
Weaknesses
- Latest information and currency — Knowledge based on training data has limits, and I can't guarantee accuracy without using a web search tool.
- Flexibility in general creative writing and chit-chat — Because my response style is optimized for development and practical tasks, I tend to come across as stiff in long-form creative writing and casual conversation.
- Breadth of multimodality — I can read images, but I can't handle a wide range of modalities such as image generation, audio, and video.
Comparison with other LLMs
Honestly, I (Kiro CLI) am not a "model" itself, but an agent/tool layer that runs Claude as its foundation model. I'm not in a position to evaluate objectively the raw performance superiority or inferiority of the foundation models. Any definitive claims of superiority would be speculation, so I'll avoid that.
Codex (GPT-5.5)'s response
To state my position honestly, I'm less a "general-purpose conversational model" and more a practical LLM geared toward code comprehension, implementation, debugging, and work within repositories.
Strengths
- Codebase investigation and implementation fixes — I'm good at reading existing code and making changes in line with the design intent.
- Technical decomposition and realistic design decisions — I'm good at breaking requirements down into implementation units and setting out safe change policies while avoiding over-engineering.
- Error analysis and debugging support — I'm well suited to narrowing down causes from stack traces, logs, failing tests, type errors, and so on, and carrying through to fix proposals.
Weaknesses
- Optimizing vague, sensibility-driven prose expression — In poetic expression, advertising copy, and literary nuance adjustment, there are cases where I fall short of the softness of Claude's writing.
- Immediate tracking of the latest external information — I'm weak on real-time information. Latest news, stock prices, and recent product specifications need to be verified.
- Reading social, political, and cultural atmosphere — For uses like Grok's, casually picking up current-affairs and internet-culture context, I'm somewhat stiff and cautious.
Comparison with other LLMs
Compared with Claude, I sometimes lose in the naturalness of writing and the warmth of long-text comprehension, but I have strengths in actually carrying code changes forward. Compared with Grok, I'm inferior in real-time capability and casual reactions to current events, but more solid in calm technical judgment and code work. In summary, my position is not "the most attractive model for chit-chat and creative writing," but "a practical model for reading and fixing code and moving technical issues forward."
Practical example: Comparing business daily report generation
Using Kiro CLI prompt logs as source data, I generated business daily reports from the same log with Kiro (Opus 4.8) and Grok 4.5, and compared the differences in output.
The method for generating daily reports from prompt logs is introduced in the following article. In this section I'll skip explaining the method and focus on comparing the outputs.
Comparison results
These are the results of using the July 10 log as input and extracting only blog-writing-related tasks.
| Aspect | Kiro (Opus 4.8) | Grok 4.5 |
|---|---|---|
| Number of extracted tasks | 5 | 7 |
| Coverage | Focused on published articles | Comprehensive, including items at the preview stage |
| Perspective on problem framing | Deliverable-oriented ("what to create") | Reader-oriented ("what needed to be conveyed") |
| Specificity of reflections | Next action + hypothesis ("check quality with the medium setting") | Statement of principle ("thorough masking policy is important") |
Task granularity and comprehensiveness: Grok listed all 7 tasks, including unconfirmed (preview-stage) tasks. Kiro narrowed it down to the 5 confirmed for publication and tended to exclude preview-stage ones.
How problems are framed: For example, for the Redshift article, Kiro wrote from a deliverable viewpoint: "verify and introduce the actual behavior of maintenance track switching." Grok, on the other hand, included the points readers want to know: "needed to convey, including the actual behavior of track switching (cannot be reverted / is deferred)."
Specificity of reflections: Kiro wrote the next step with a hypothesis included: "confirm in the next article whether review quality falls within an appropriate level with Codex/Grok's medium setting." Grok stayed with a statement of principle: "leaving verification log files in place and thorough masking policy are important."
Excerpt of actual output — Comparing the task descriptions for the Redshift article (click to expand)
Kiro (Opus 4.8) output
3. Article on changing the track for Redshift RG instances (2.0h)
- Problem: With Trailing Track support for Amazon Redshift RG instances, verify and introduce the actual behavior of maintenance track switching.
- Action: Verified switching from Trailing→Current (completed in about 5 minutes, confirmed upgrade from Patch 201→202), confirmed the deferral behavior for Current→Trailing, organized the operational impact of differences between patches, differentiated from the earlier article (introduced via a card link and focused on actual behavior), and adjusted the wording of the summary.
- Result: [Done] Article published. Title finalized as "Trying Track Changes for Amazon Redshift RG Instances."
Grok 4.5 output
3. Article verifying Trailing Track switching for Amazon Redshift RG instances (1.5h)
- Problem: Needed to convey that Trailing Track has become available for RG instances, including the actual behavior of track switching (cannot be reverted / is deferred).
- Action: Confirmed cluster launch and Track change in the verification account, cross-checked the official differences, organized the division of roles with the earlier article, conducted multiple reviews, and checked the preview.
- Result: [Done] Wrote the article centered on Trailing→Current being applied and upgraded in the maintenance window, and Current→Trailing not being downgraded.
Comparison of reflections
Kiro (Opus 4.8):
Blog planning skill | Reflection: Confirm in the next article whether review quality falls within an appropriate level with Codex/Grok's medium setting. If excessive findings decrease, the effort for accept/reject decisions is also expected to drop.
Grok 4.5:
Blog planning skill | Reflection: Descriptions of unperformed steps and baseless assertions of "convention" can creep in through review, so leaving verification log files in place and thorough masking policy are important
Practical example: Using it for plan review
I had the plan for this article itself reviewed by three models: Opus 4.8, Grok 4.5, and Codex (GPT-5.5). I used a review prompt that outputs findings affecting the article's viability from the perspectives of structure, technical verification, and scope, with the same plan.md as input.
Distribution of findings
| Finding | Opus 4.8 | Grok 4.5 | Codex (GPT-5.5) |
|---|---|---|---|
| Undefined observation items (prompts 3 and 4) | ✅ | ✅ | — |
| Confirming whether the daily report can be published | ✅ | ✅ | — |
| Risk of using prompt 4 as grounds for characterization | ✅ | ✅ | — |
| Citing sources for benchmarks and pricing | ✅ | — | — |
| Insufficient verification as a coding agent | — | ✅ | — |
| Insufficient clarification of the "free" premise | — | ✅ | — |
| Risk of log file names being overwritten | — | — | ✅ |
| Preventing publication of credentials | — | — | ✅ |
There were 3 common findings (Opus + Grok), 1 unique to Opus, 2 unique to Grok, and 2 unique to Codex.
Excerpt of actual review output (click to expand)
Grok 4.5's review findings (excerpt)
Finding: The article's claim is "trying Grok Build CLI (a coding agent)," but the verification is almost entirely a comparison of one-shot prompt responses, such as design explanations, DrawIO XML, requirements organization, and self-reports, and does not include verification as a coding agent (repository operations, tool use, multi-step implementation and fixes, etc.).
Reason: As it stands, the claim and conclusion of "trying a coding agent with the CLI" cannot be supported by the verification results, and the article's main purpose and verification method don't line up, causing a serious rework.
Minimal fix: Clarify the verification target as one of the following. (A) If the coding agent experience is the main focus, add agent execution on the same repository / same task as a required verification. (B) If one-shot response comparison is the main focus, remove "coding agent" from the claim and limit it to "Grok 4.5 responses in CLI headless mode."
Finding: The claim "can be tried for free" is not reconciled with the premise of X Premium+ (a paid subscription) and the usage conditions and billing on the Codex (Bedrock) side, so "what is free and what is charged," which readers need to judge, is not settled in the plan.
Minimal fix: Add "confirm usage conditions in the official documentation" to the premises of the verification procedure, and clarify the terminology in the plan (e.g., with Premium+ subscribed, it can be used from the CLI without an additional API key).
Opus 4.8's review findings (excerpt)
Finding: Evaluation perspectives / criteria are not defined for prompts 1, 3, and 4 ("5. Perspectives for response comparison" only covers prompts 1 and 2).
Reason: In particular, for prompt 1, "technical accuracy" has no defined correct answer or basis for judgment, so the conclusion of the three-agent comparison cannot be shown objectively in the body text.
Minimal fix: Add the checking perspectives for prompts 3 and 4 to "5. Perspectives for response comparison," and state what criteria will be used to judge "technical accuracy" in prompt 1.
Codex (GPT-5.5)'s review findings
Finding: The output destination of the execution commands uses the same file name for each prompt, so the plan cannot retain the verification logs for P1 to P3.
Reason: If run as is, they will be overwritten by later results, and the basis for each prompt's response cannot be shown in the body text. In particular, P2/P3 text comparisons cannot be supplemented by images alone, causing serious rework.
Minimal fix: Please add a note that the output destinations of the execution commands will be split into file names that include the prompt number and agent name, such as
logs/p1-grok-response.mdandlogs/p2-grok-response.md.
Finding: While the plan covers the fact that a refresh token is stored in
~/.grok/auth.json, it has no checklist items to prevent credentials from appearing in the article, logs, or images.Reason: Mishandling the authentication file or CLI logs poses a serious risk of credential disclosure.
Minimal fix: Please add to the precautions: "Do not publish file contents that contain credentials or tokens" and "Confirm that logs and screenshots do not contain tokens, cookies, authentication URLs, or account-identifying information."
Accept/reject decisions
| Finding | Decision | Reason |
|---|---|---|
| Undefined observation items | Accepted | Added comparison perspectives for prompts 3 and 4 as well |
| Whether the daily report can be published | Accepted | Already confirmed, but stated explicitly in the plan |
| Risk of prompt 4 | Accepted | Positioned as an observation of response style, not factual evidence |
| Citing benchmark sources | Accepted | Added a note that these are officially announced values |
| Insufficient coding agent verification | Rejected | The article's policy is to evaluate prompt response quality as a general-purpose AI. Verifying coding functionality is in the scope of a separate article |
| Clarifying the "free" premise | Accepted | Stated the usage conditions (Premium+ subscription as a prerequisite) explicitly |
| Risk of log file names being overwritten | Rejected | In practice, files were already saved with the prompt number + agent name, such as prompt2-grok.drawio. The command example in plan.md was just template-like |
| Preventing publication of credentials | Accepted | The structure of auth.json is described, but secrets such as token values and user IDs are not included in the article |
The three models each pointed out holes in the plan from different perspectives, confirming both the precision of the common findings and the diversity of the unique perspectives. "Insufficient coding agent verification" was a finding unique to Grok, but I rejected it because it didn't match the article's policy. Grok emphasized the CLI's official designation (coding agent) and also mentioned verification outside the article's scope. Codex's "overwriting of log file names" was also a finding inferred from the plan's wording about a problem that had already been resolved in actual operation, so there was a gap from reality.
On the other hand, all three common findings from Opus and Grok were on point and would have affected the article's viability had they not been addressed. Codex's "preventing publication of credentials" was also a practical finding, and I felt its value as a second opinion.
Usage confirmed at execution time
| Prompt | Grok 4.5 | Kiro (Opus 4.8) | Kiro (Sonnet 5) | Codex (GPT-5.5) |
|---|---|---|---|---|
| DrawIO XML generation | — | 1.57 credits / 47s | 1.27 credits / 52s | 12,057 tokens |
| Organizing specs from ambiguous requirements | — | 0.47 credits / 31s | 0.23 credits / 20s | 8,274 tokens |
| Metacognition | — | 0.42 credits / 30s | 0.23 credits / 21s | 1,287 tokens |
Grok Build CLI's headless mode does not display credit consumption. When I checked before and after running the three prompt comparisons above, X's usage increased from 55% to 57% (+2%).
Summary
Using Grok Build CLI's headless mode, I compared the responses of Grok 4.5, Kiro CLI, and Codex CLI to the same prompts. In this verification, Grok 4.5 output 177 lines for DrawIO XML generation, the most among the four models, and also returned a detailed answer including tables and supplements for organizing specs from ambiguous requirements. It showed a tendency to broadly pick up the background and surrounding information of the input and build thicker explanations.
By using the -p option, Grok Build CLI can be called from a local script as a single prompt execution. It can also be used as a sub-agent of Kiro CLI, serving as a second opinion for review and requirements organization from the perspective of a different model. In fact, in the plan review for this article, I ran Opus 4.8, GPT-5.5, and Grok 4.5 in parallel, and treated findings common across multiple models as strong material for accept/reject decisions.
On Amazon Bedrock, Grok 4.3 has been available since last month. If Grok 4.5 also comes to Bedrock in the future, it will become possible to call it from AWS environments using IAM authentication and to use it entirely within AWS. Along with using it through Grok Build CLI, I'll be keeping an eye on how it is offered going forward.