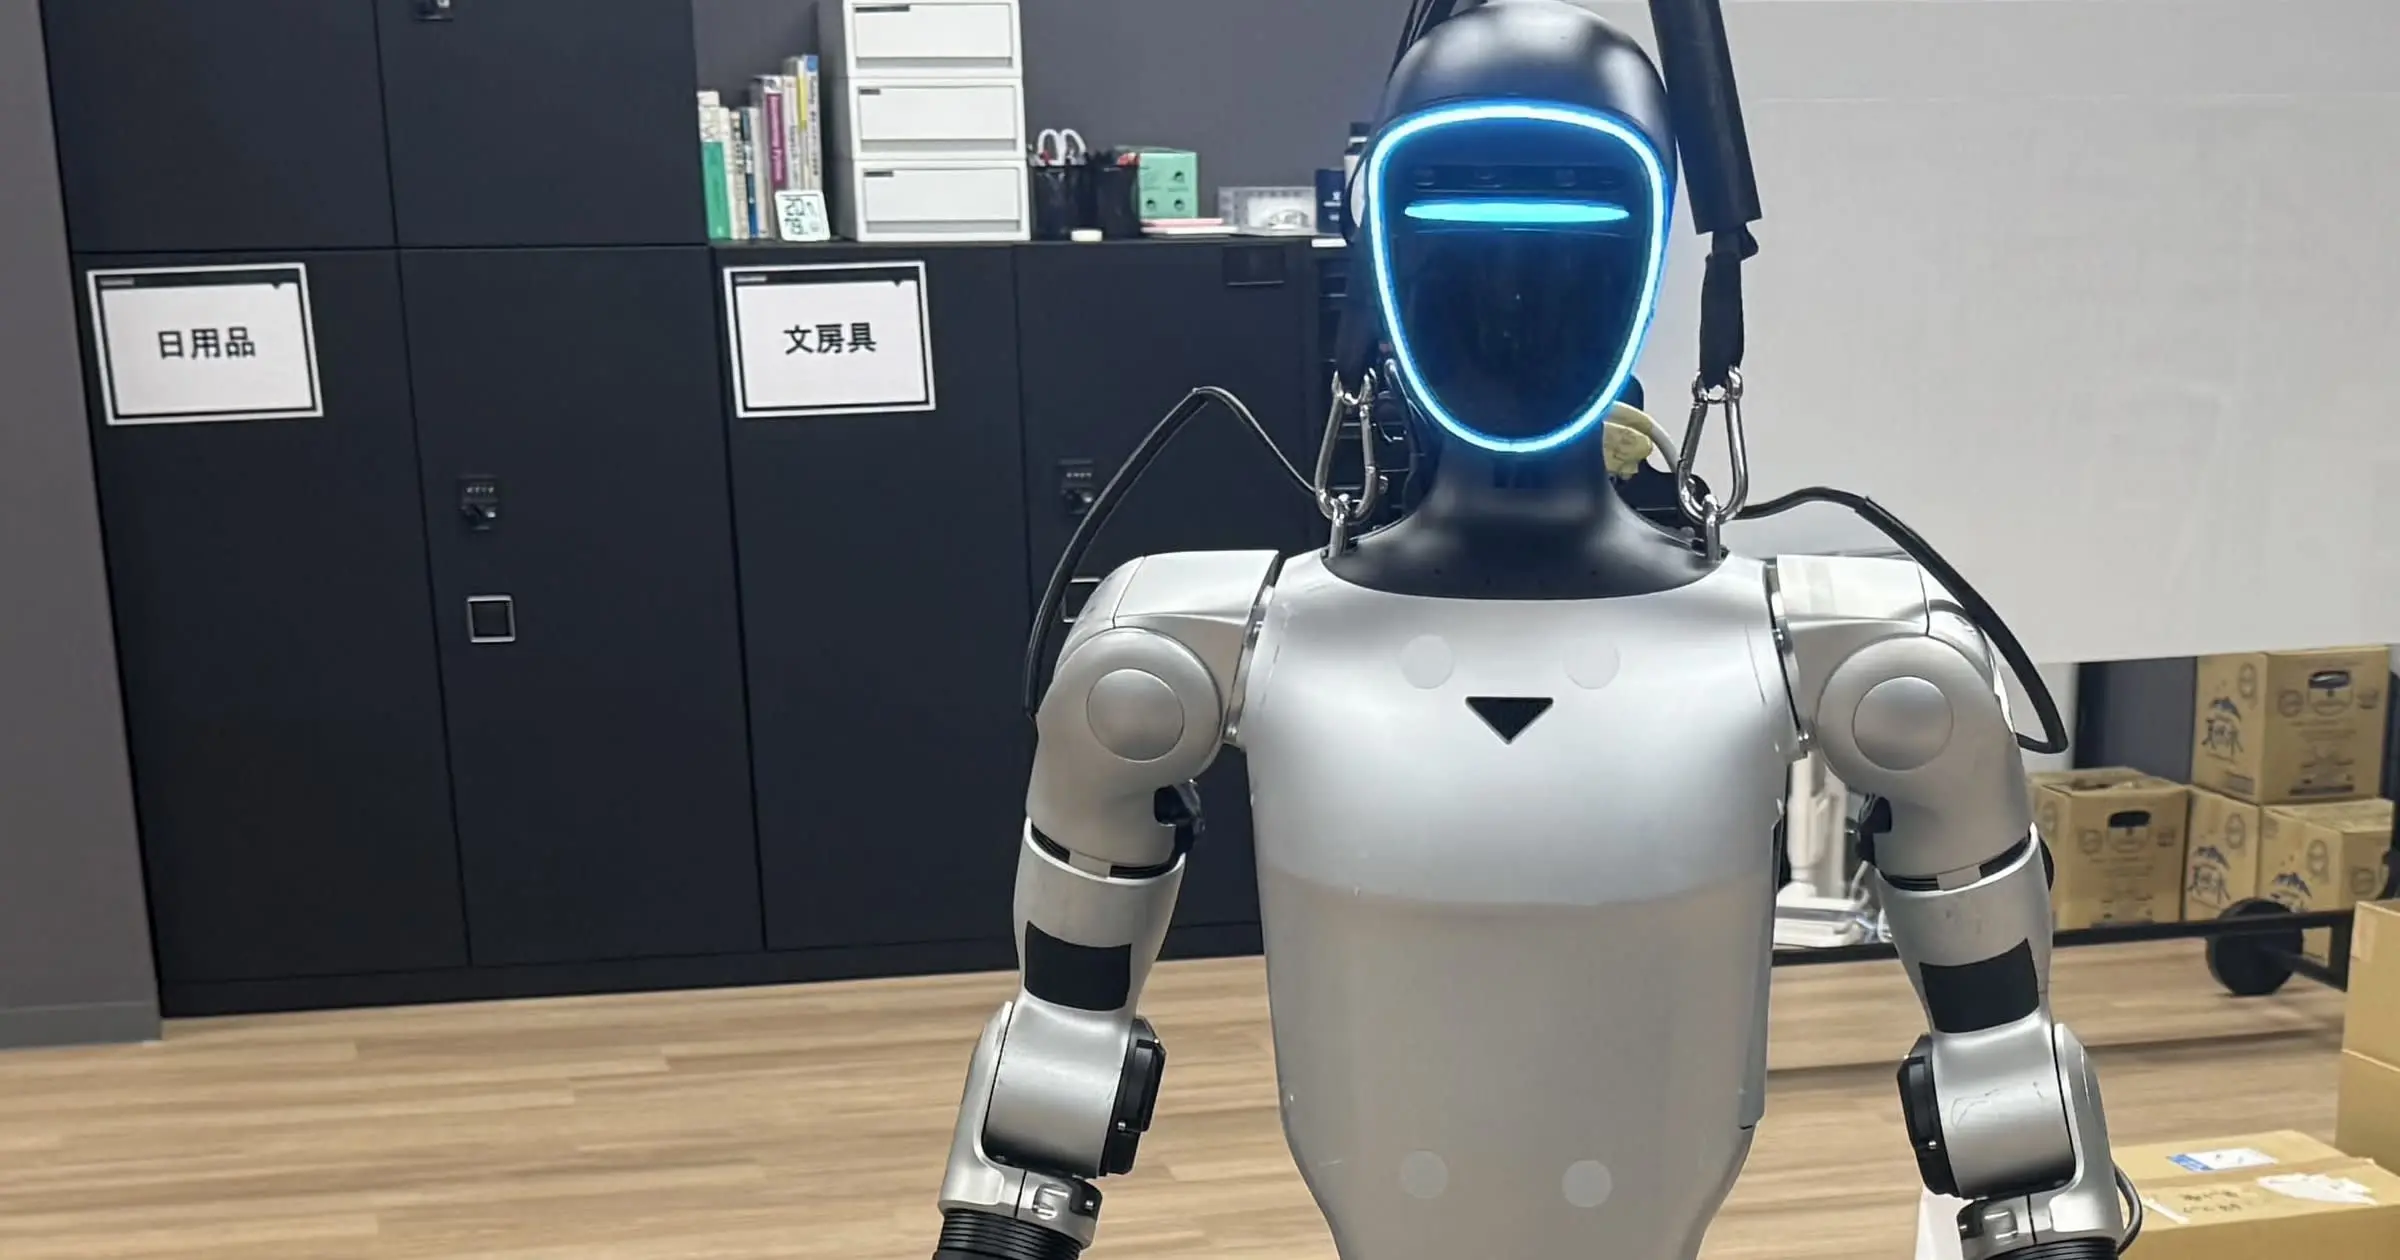
Getting Started with a Unitree G1 Bottle Grasping and Lifting Reinforcement Learning Project Using Isaac Lab and PPO: Object-Relative Correction and Integration with DGX Spark and the Real Robot

This page has been translated by machine translation. View original
Introduction
In the previous article, I introduced a reinforcement learning project for bottle grasping and lifting with the Unitree G1 Inspire Hand, covering the following:
- Mass Curriculum from 0.08 kg to 0.62 kg
- Stage 2 grasp / lift policy adapted to the 0.62 kg condition
- Stage 1 Safe Approach Policy that approaches without moving the dynamic bottle
- Controlled ingress connecting Stage 1 and Stage 2
- Phase timing issue caused by Isaac Lab decimation
- Verification of checkpoint architecture and observation contract
- Termination-based formal deterministic evaluation
The main simulation results up to the previous article were as follows.
| Module | Condition | Result |
|---|---|---|
| Stage 1 | Dynamic 0.62 kg, x/y ±1.5 cm | 768 / 768 |
| Stage 2 | Fixed nominal, 0.62 kg | 766 / 768 |
| Zero-residual bridge | Fixed nominal | Reached Stage 2 handover |
However, as of the previous article, the integrated evaluation running the Stage 2 learned residual from the actual Stage 1 handover state had not been completed.
This week, after completing this integration, I worked on failure analysis of the randomized workspace, object-relative trajectory correction, and extension to a wider workspace.
I also migrated the trained checkpoints to NVIDIA DGX Spark and built a standalone actor that does not depend on Isaac Lab. After that, I verified step by step: state acquisition from the real Unitree G1 and Inspire Hand, right-arm transition to the task-ready pose, finger motion in the air, and finally the first bounded model-derived command.
This article summarizes the following.
- Nominal integration with the learned Stage 2 connected
- Coordinate semantics problem found in integrated RandPos
- Object-relative ingress / lift correction
- Success rate improvement from 55.7% to 97.4% under the ±1.5 cm condition
- ±5 cm workspace and Stage 0 coarse bias
- 84.4% success in a practical asymmetric workspace
- Checkpoint migration to DGX Spark
- Rebuilding the standalone PyTorch actor
- Inference agreement between Brev x86 and DGX Spark ARM64
- Initial integration with the real G1 / Inspire Hand
- Failures encountered this week and implementation notes
- Current status and remaining challenges
The success rates in this article are simulation results using a simplified rigid-body bottle in Isaac Lab.
The real-robot content consists of staged verification performed with a fixed standing posture, under supervision, at low speed, with no object or a lightweight empty bottle. It does not demonstrate autonomous grasping or lifting of an actual beverage bottle, sim-to-real transfer, human handover, or safety certification.
Connecting the Learned Stage 2 to the Integrated Pipeline
Last time, I confirmed that Stage 2 can be reached from Stage 1 via controlled ingress.
In the first bridge diagnostic, the Stage 2 residual was set strictly to zero.
learned Stage 1
  ↓
controlled ingress
  ↓
scripted Stage 2 base trajectory
  + zero residual
With this configuration, the safe handover succeeded, but the 0.62 kg bottle could not be lifted to a meaningful height.
Representative results were as follows.
| Metric | Result |
|---|---|
| Maximum center-height increase | approximately 4.8 mm |
| Final center-height increase | approximately 0.04 mm |
| Maximum horizontal displacement | approximately 43 mm |
| Strict retention / lift | False |
In other words, the geometry bridge from Stage 1 to Stage 2 held, but grasp / retention under the 0.62 kg condition required the learned residual.
So I connected the selected Stage 2 checkpoint to the integrated environment.
Stage 1:
  frozen deterministic policy

controlled ingress:
  deterministic arm interpolation

Stage 2:
  scripted base trajectory
  + frozen deterministic 12D hand residual
Stage 2 actor inference runs only once per environment step, not at every physics substep.
environment step:
  actor inference
  previous residual update
  target calculation

remaining physics substep:
  hold the same target
This is as important as the decimation issue found last time.
If actor inference or the previous residual update runs at every physics substep, the policy operates on a different time scale than during training.
After the fix, the Stage 2 actor inference count matched the expected value.
actual inference count:
  742

expected inference count:
  742
Under the nominal condition, enabling the Stage 2 learned residual produced a meaningful lift of about 3.58 cm.
However, if the policy target kept being updated after a successful lift, the bottle sometimes tilted over time and eventually slipped.
Target Latch After a Successful Lift
The formal success criterion requires all of the following to hold continuously for a set period.
- bottle height
- retention
- workspace
- uprightness
- safety condition
In this setup, 24 consecutive valid steps was used as the formal success condition.
Once success is reached, I added a supervisory latch that stores the last commanded hand target and keeps holding it.
retention / lift success
  ↓
copy current commanded hand target
  ↓
stop updating hand target
  ↓
continue normal physics simulation
This latch fixes only the command target.
The following operations were not performed.
- bottle attachment
- bottle freeze
- kinematic override
- teleport
- physics pause
- direct modification of the object pose
Representative results after the latch were as follows.
| Metric | Result |
|---|---|
| Commanded-target drift | 0.000000000 |
| Final retention count | 423 |
| Final center-height increase | approximately 0.0358 m |
| Final uprightness | approximately 0.969 |
This confirmed the following sequence under the nominal condition.
Stage 1 outer approach
  ↓
controlled ingress
  ↓
Stage 2 grasp
  ↓
lift
  ↓
retention
  ↓
stable extended hold
However, this result is hybrid control.
learned Stage 1
  + deterministic geometric bridge
  + learned Stage 2
  + supervisory target latch
It is not pure end-to-end RL.
The First Integrated RandPos Result Was 55.7%
Once nominal integration worked, I ran the integrated RandPos evaluation, varying the bottle position by ±1.5 cm in x/y.
The conditions were as follows.
bottle:
  dynamic simplified rigid body
  0.62 kg

randomization:
  x/y ±0.015 m

Stage 1:
  frozen model_149

ingress / lift:
  fixed nominal joint-space targets

Stage 2:
  frozen model_100

success:
  24-step retention / lift success
  by termination_manager
The results were as follows.
| Seed | Success |
|---|---|
| 42 | 145 / 256 |
| 43 | 283 / 512 |
| Combined | 428 / 768 |
The combined success rate was 55.73%.
The failure distribution was as follows.
| Outcome | Count | Rate |
|---|---|---|
| Success | 428 | 55.73% |
| Unsafe bottle disturbance | 197 | 25.65% |
| Object out of workspace | 43 | 5.60% |
| Timeout | 100 | 13.02% |
Stage 1 scored 768/768 in isolation and Stage 2 scored 766/768 under the fixed condition.
Nevertheless, the integrated result was 428/768.
This shows that multiplying the individual policies' success rates does not give the integrated success rate.
The Problem Was Coordinate Semantics, Not Policy Performance
Looking at the failure map, the failures were not random but showed directionality depending on bottle position.
In the failure analysis of 1024 episodes, 233 of 234 unsafe failures occurred in the region where the bottle's y offset was negative.
Timeout and workspace failures also increased on the positive x side.
From this, I suspected a geometric inconsistency rather than simple PPO noise.
Stage 1 Was Bottle-Relative
The Stage 1 target is computed from the bottle position.
outer_target
  = bottle_position + outer_offset
So even when the bottle moves, Stage 1 can move to the same relative position with respect to the bottle.
Ingress and Lift Used the Nominal Joint Pose
On the other hand, the ingress and lift after Stage 1 used fixed joint-space targets.
Stage 1:
  tracks the displaced bottle

ingress:
  returns to nominal joint pose

lift:
  returns to nominal joint pose
In other words, things were object-relative up to Stage 1, but the subsequent trajectory lost object-relative semantics.
bottle-relative outer pose
  ↓
fixed nominal ingress
  ↓
fixed nominal lift
This causes the hand to return to a position off the bottle when the bottle position shifts by a few cm.
The key point is that before retraining checkpoints or PPO, you need to check that coordinate semantics are consistent across the whole controller.
Even if the learned policy is object-relative, if the scripted controller afterward returns to nominal joint-space, the system as a whole is not object-relative.
Object-Relative Correction via the Local Jacobian
To solve this problem, I numerically measured the hand-center Jacobian around the nominal ingress pose.
The target joints are the following four.
- right shoulder pitch
- right shoulder roll
- right shoulder yaw
- right elbow
The hand center is the mean position of the following four proximal links.
- index proximal
- middle proximal
- ring proximal
- pinky proximal
The conversion from Cartesian displacement to joint correction used the pseudoinverse of the measured Jacobian.
bottle_offset = settled_bottle_position - nominal_bottle_position

desired_hand_translation = gain × [offset_x, offset_y, 0]

joint_correction = Cartesian-to-arm pseudoinverse × desired_hand_translation
The corrected targets are as follows.
corrected_ingress_target = nominal_ingress_target + joint_correction

corrected_lift_target = nominal_lift_target + joint_correction
Applying the same correction to both ingress and lift keeps the object-relative geometry even after grasping starts.
The measured matrix had roughly the following characteristics.
| Joint | x direction | y direction |
|---|---|---|
| Shoulder pitch | -5.28 rad/m | -1.08 rad/m |
| Shoulder roll | +0.32 rad/m | +1.21 rad/m |
| Shoulder yaw | -1.79 rad/m | +1.66 rad/m |
| Elbow | +5.40 rad/m | +1.42 rad/m |
The RMSE of the Jacobian fit was about 0.036 mm.
However, this is a local model around the nominal ingress pose.
It does not mean it can be extrapolated directly to ±10 cm or ±15 cm.
Comparing Correction Gains
I compared correction gains under the x/y ±1.5 cm condition.
| Gain | Success |
|---|---|
| 0.00 | 82 / 128 |
| 0.50 | 116 / 128 |
| 0.75 | 124 / 128 |
| 1.00 | 126 / 128 |
I selected gain 1.0 and ran the formal evaluation.
The following were left unchanged.
- Stage 1 checkpoint
- Stage 2 checkpoint
- PPO weight
- observation
- residual scale
- self-collision
- bottle physics
- formal success condition
- unsafe threshold
No additional training was performed.
97.4% Success at ±1.5 cm
The formal evaluation results with object-relative ingress / lift correction enabled are as follows.
Seed 42
| Outcome | Result |
|---|---|
| Success | 253 / 256 |
| Unsafe | 0 |
| Workspace | 0 |
| Timeout | 3 |
Seed 43
| Outcome | Result |
|---|---|
| Success | 495 / 512 |
| Unsafe | 0 |
| Workspace | 3 |
| Timeout | 14 |
Combined
| Outcome | Result | Rate |
|---|---|---|
| Success | 748 / 768 | 97.40% |
| Unsafe | 0 / 768 | 0% |
| Workspace | 3 / 768 | 0.39% |
| Timeout | 17 / 768 | 2.21% |
Comparing before and after the correction:
| Metric | Before | After |
|---|---|---|
| Success | 428 | 748 |
| Success rate | 55.73% | 97.40% |
| Unsafe | 197 | 0 |
| Total failures | 340 | 20 |
Successes increased by 320 episodes.
Failures dropped from 340 to 20, a reduction of about 94.1%.
Without any additional PPO, just fixing the coordinate semantics improved the success rate by 41.67 percentage points.
This was the most important result this week.
Before adding more policies, check that frame and target semantics agree between learned control and geometric control.
Extending the Workspace to ±5 cm
Next, I extended the bottle position range to x/y ±5 cm.
First, I evaluated with only the same object-relative correction and without adding Stage 0.
The results were as follows.
| Outcome | Count | Rate |
|---|---|---|
| Success | 536 / 768 | 69.79% |
| Unsafe | 20 / 768 | 2.60% |
| Workspace | 2 / 768 | 0.26% |
| Timeout | 210 / 768 | 27.34% |
The conditional success after reaching Stage 2 was about 91.94%.
Stage 2 reached:
  583 / 768

success after Stage 2:
  536 / 583
In other words, once Stage 2 was reached, grasp / lift succeeded in most episodes.
The main bottleneck was that Stage 1 could not reach the outer gate in the wide workspace.
The positive y direction was particularly weak, and in the y=+4 to +5 cm bin the results were:
samples:
  51

outer gate:
  0 / 51

success:
  0 / 51
In this region, the target could not be reached even with longer episode durations.
Stage 0 Coarse Bias
The Stage 1 policy was originally trained with a local capture range of ±1.5 cm.
So I added a deterministic Stage 0 before Stage 1.
The purpose of Stage 0 is to remove only the part of the wide workspace offset that exceeds the Stage 1 local range.
bottle_offset
  ↓
local_offset
  = clamp(bottle_offset, -0.015, +0.015)

coarse_translation
  = bottle_offset - local_offset

Stage 0 bias = safe-pose Jacobian pseudoinverse × coarse_translation
The execution order is as follows.
Stage 0:
  60-step smooth coarse motion
  ↓
Stage 1:
  frozen local safe approach
  ↓
object-relative ingress / lift
  ↓
Stage 2
Stage 0 is not a learned policy but a geometric controller using the measured local Jacobian around the safe pose.
The selected settings are as follows.
local capture half-range:
  0.015 m

coarse steps:
  60

correction bound:
  0.24 rad
Full ±5 cm Square Results
The formal evaluation results for the full x/y ±5 cm square with Stage 0 enabled were as follows.
Seed 42
success:
  193 / 256
  75.39%
Seed 43
success:
  376 / 512
  73.44%
Combined
| Outcome | Count | Rate |
|---|---|---|
| Success | 569 / 768 | 74.09% |
| Unsafe | 16 / 768 | 2.08% |
| Workspace | 21 / 768 | 2.73% |
| Timeout | 162 / 768 | 21.09% |
Comparison with the no-Stage-0 case is as follows.
| Metric | Without Stage 0 | With Stage 0 |
|---|---|---|
| Outer gate reached | 601 | 750 |
| Stage 2 reached | 583 | 737 |
| Success | 536 | 569 |
Stage 0 fixed most of the Stage 1 reach failures.
On the other hand, the success rate after reaching Stage 2 dropped to about 77.2%.
In other words, once Stage 0 made the target reachable, the next bottleneck shifted to handover geometry at wide positions and Stage 2 compatibility.
Failure Analysis in the Positive-y Region
Analyzing the 162 timeouts in the full square, 147 of them had reached Stage 2.
The mean initial positions of success episodes and timeout episodes showed the following tendency.
| Outcome | Mean x | Mean y |
|---|---|---|
| Success | -0.0014 m | -0.0106 m |
| Timeout after Stage 2 | +0.0088 m | +0.0248 m |
| Workspace failure | +0.0244 m | +0.0093 m |
I thought that on the positive y side the grasp geometry tends to fall outside the Stage 2 training distribution.
So I tried the following.
- global ingress gain
- positive-y trim
- pre-contact alignment
Global Gain 1.04
At fixed y=+5 cm, gain 1.04 sometimes succeeded.
However, it got worse in the paired wide evaluation.
| Gain | Success |
|---|---|
| 1.00 | 204 / 256 |
| 1.04 | 194 / 256 |
A parameter that works at a fixed point is not necessarily effective over the whole workspace.
Positive-y Trim
In a paired comparison using the first episode per environment, trim gave no stable improvement.
| Trim | Success / 128 |
|---|---|
| 0 mm | 97 |
| 1 mm | 91 |
| 2 mm | 96 |
| 3 mm | 98 |
Some conditions also increased unsafe disturbance, so I did not adopt it.
Pre-contact Alignment
I also tried extra alignment using the error between hand center and bottle center.
At fixed y=+5 cm some gains succeeded, but the wide paired evaluation showed no improvement.
alignment off:
  97 / 128

y-only gain 0.25:
  95 / 128
From this, I decided not to adopt fixed-point improvements as global corrections.
Choosing a Practical Workspace Instead of a Symmetric Square
The full ±5 cm square is a useful comparison condition for research.
However, there is no need to insist on a perfect square that includes the far edge of positive y.
In post-hoc analysis of the full-square evaluation, the following workspace showed comparatively good results.
x:
  [-0.05, +0.05] m

y:
  [-0.05, +0.03] m
This is an asymmetric workspace 10 cm wide and 8 cm deep.
However, a post-hoc mask alone cannot be called a formal result.
So I implemented this range as an explicit randomization distribution and ran a prospective evaluation.
84.4% in the Practical Asymmetric Workspace
The selected workspace is as follows.
bottle x:
  [-0.05, +0.05] m

bottle y:
  [-0.05, +0.03] m

size:
  10 cm × 8 cm
The controller configuration is as follows.
Stage 0:
  enabled

Stage 1:
  frozen model_149

ingress / lift:
  object-relative correction
  gain 1.0

Stage 2:
  frozen model_100

positive-y trim:
  disabled

pre-contact alignment:
  disabled
The formal evaluation results were as follows.
Seed 42
| Outcome | Result |
|---|---|
| Success | 209 / 256 |
| Success rate | 81.64% |
| Unsafe | 2 |
| Workspace | 3 |
| Timeout | 42 |
Seed 43
| Outcome | Result |
|---|---|
| Success | 439 / 512 |
| Success rate | 85.74% |
| Unsafe | 2 |
| Workspace | 11 |
| Timeout | 60 |
Combined
| Outcome | Count | Rate |
|---|---|---|
| Success | 648 / 768 | 84.375% |
| Unsafe | 4 / 768 | 0.52% |
| Workspace | 14 / 768 | 1.82% |
| Timeout | 102 / 768 | 13.28% |
The phase results are as follows.
| Phase | Count | Rate |
|---|---|---|
| Outer gate reached | 764 / 768 | 99.48% |
| Ingress started | 764 / 768 | 99.48% |
| Stage 2 reached | 763 / 768 | 99.35% |
| Success after Stage 2 | 648 / 763 | 84.93% |
With this result, the original goal of 80% integrated success was exceeded in an explicitly defined practical workspace.
Separating the Three Kinds of Results
These results need to be recorded separately by workspace condition.
| Level | Workspace | Result |
|---|---|---|
| High-reliability local | x/y ±1.5 cm | 748 / 768, 97.40% |
| Full symmetric square | x/y ±5 cm | 569 / 768, 74.09% |
| Practical asymmetric | x ±5 cm, y -5 to +3 cm | 648 / 768, 84.375% |
These are not the same result.
- ±1.5 cm is the most reliable local result
- The full ±5 cm square is a research result below 80%
- 10 cm × 8 cm is a practical result that exceeded 80% in a prospective evaluation
What matters is that I did not merely exclude the weak regions of the full square post hoc, but re-evaluated it as a separate distribution.
Why I Did Not Run Additional PPO
In this round of improvements, I did not change the Stage 1 and Stage 2 checkpoints.
selected Stage 1:
  model_149

selected Stage 2:
  model_100
The reason I did not run additional PPO is that the main failures were not due to insufficient policy capacity but to the following.
- object-relative semantics mismatch
- wide offset inputs to the local policy
- Stage 1 reach range
- handover difference from the Stage 2 training distribution
- phase / timing implementation
Continuing PPO might absorb some of the failures.
However, adding training while the controller's frame semantics are wrong would make the policy learn the inconsistency of the system design.
The large improvement this time came from fixing system integration, not from additional training.
frozen learned Stage 1
  + measured geometric correction
  + optional Stage 0
  + frozen learned Stage 2
  + supervisory hold
This is a hybrid learned-plus-geometric control system.
Migrating the Checkpoints to DGX Spark
After fixing the simulation milestone, I migrated the trained checkpoints to NVIDIA DGX Spark.
The goal is not to run Isaac Sim or Isaac Lab on DGX Spark.
simulator:
  runs in the Isaac Lab environment

DGX Spark:
  standalone actor inference
  robot state adapter
  safety supervisor
  logging
  future perception runtime
The selected checkpoints are as follows.
Stage 1
input:
  24D

network:
  24 → 128 → 64 → 4

activation:
  ELU
Stage 2
input:
  53D

network:
  53 → 256 → 128 → 64 → 12

activation:
  ELU
I extracted only the actor part from each checkpoint and rebuilt it as a standalone PyTorch network.
This runtime does not require the following.
- Isaac Sim
- Isaac Lab
- Omniverse
- ManagerBasedRLEnv
- RSL-RL runtime
Comparing Inference Results on x86 and ARM64
Even if the checkpoint binary can be copied, it does not necessarily produce the same inference results on a different architecture.
So I compared actor outputs for the same input tensors on the x86 environment on Brev and the ARM64 environment on DGX Spark.
The comparison used the following.
- zero observation
- deterministic synthetic probe
- actor mean output
- tolerance 1e-6
The results were as follows.
| Actor | Input | Maximum absolute difference |
|---|---|---|
| Stage 1 | Zero | 2.98e-8 |
| Stage 1 | Probe | 1.49e-8 |
| Stage 2 | Zero | 2.98e-8 |
| Stage 2 | Probe | 1.19e-7 |
All were within 1e-6.
This confirmed the following.
- checkpoint integrity
- actor architecture reconstruction
- layer order
- activation function
- deterministic inference
- x86 / ARM64 numerical parity
However, this parity only proves that actor outputs match for the same input tensor.
It does not prove the following.
- real-world observation equivalence
- real robot action mapping
- real camera accuracy
- real grasp success
- real Jacobian validity
The Observation Contract Matters in the Real Runtime
To run a standalone actor, the checkpoint and network architecture are enough.
However, to connect the policy to the real robot state, the meaning of the observations must be reproduced exactly.
Stage 1 Observation
Stage 1 is 24D.
| Term | Dimension |
|---|---|
| Right-arm absolute joint position | 4 |
| Right-arm joint velocity | 4 |
| Hand-center position | 3 |
| Hand-center linear velocity | 3 |
| Bottle position | 3 |
| Hand-center to outer-target vector | 3 |
| Previous raw action | 4 |
| Total | 24 |
Stage 2 Observation
Stage 2 is 53D.
| Term | Dimension |
|---|---|
| Right-hand articulated joint position | 12 |
| Right-hand joint velocity | 12 |
| Hand-center position | 3 |
| Bottle position | 3 |
| Bottle quaternion wxyz | 4 |
| Bottle linear velocity | 3 |
| Bottle minus hand-center | 3 |
| Retention phase | 1 |
| Previous raw residual | 12 |
| Total | 53 |
Even if the observation dimensions match, compatibility is lost if any of the following differ.
- term order
- coordinate frame
- quaternion order
- unit
- normalization
- timing
- previous action semantics
As with the checkpoint architecture, the observation config used during training must be treated as the source of truth.
Connecting the Inspire Hand's 6D Motor Space and the Simulator's 12D Representation
The right hand used in simulation is represented by 12 articulated joints.
On the other hand, the real RH56DFQ state obtained this time treats the right hand as a 6-dimensional motor-space state.
Checking the official DFQ URDF, 6 of the 12 articulated joints have mimic relations defined.
Representative relations are as follows.
index intermediate
  = index proximal

middle intermediate
  = middle proximal

ring intermediate
  = ring proximal

pinky intermediate
  = pinky proximal

thumb intermediate
  = 1.6 × thumb proximal pitch

thumb distal
  = 2.4 × thumb proximal pitch
Based on this mimic structure, I built an adapter that expands the 6D motor-space state into a 12D articulated representation that can be fed to the Stage 2 policy, and projects the Stage 2 output back into a 6D motor-space candidate.
real motor-space q6
  ↓
initial motor-to-joint range model
  ↓
DFQ mimic expansion
  ↓
simulator-side 12D articulated representation
  ↓
Stage 2 actor
  ↓
unilateral target q12
  ↓
least-squares projection onto DFQ manifold
  ↓
bounded motor-space q6 candidate
Within the adopted conversion model, the 6D→12D→6D roundtrip error was 0.
However, this roundtrip result only shows that the adapter's forward / inverse equations are internally consistent. It does not mean that robot-specific calibration between the real motor coordinates and the URDF joint coordinates is complete.
At this point, additional real-robot verification is needed for motor order, command / state index correspondence, range, sign, zero offset, and the scale between motor position and URDF joint angle.
Also, although visual hand motion from real commands was confirmed, no clear proportional relationship was confirmed between commanded motor changes and the expected index responses in rt/inspire/state.
Therefore, the 12D state used in this article is treated not as fully calibrated real joint angles, but as a simulator-side articulated representation based on the official DFQ mimic structure and an initial range model.
Furthermore, the simulator's SIDE_OPEN / CONTACT / SQUEEZE poses do not lie exactly on the real DFQ mimic manifold.
Therefore, when converting Stage 2 targets into motor space, I recorded the projection error, and for real commands I explicitly limited the closing direction and maximum delta.
On the Real Robot, Start from Normal Standing
The simulation safe pose and the G1's native Normal standing pose were very different.
Comparing hand centers with official-model FK, the distance from Normal standing to the simulator task-ready pose was about 51 cm.
hand-center translation:
  x approximately +0.35 m
  y approximately +0.15 m
  z approximately +0.34 m

total distance:
  approximately 0.51 m
This is not a small policy residual.
Therefore, on the real robot I added Real Stage -1 before Stage 1.
Real Stage -1:
  Normal standing
  → task-ready right-arm pose

Stage 1:
  local task approach
Rather than sending the simulation reset pose directly to the real robot, I recorded read-only the right-arm pose actually produced by the robot's native controller and used it as the task-ready candidate.
Staged Verification of Real Stage -1
Rather than raising the Arm SDK control weight all at once, I verified the following step by step.
- Current-state hold
- Low-weight bumpless takeover
- Small shoulder / elbow waypoint
- Full-weight fixed-anchor takeover
- Transition to the captured task-ready pose
- Continuous hold at the captured pose
- Controlled return
- Release to the normal controller
In the first exact-state hold, I kept commanding the fixed pose recorded at start, which conflicted with the native controller's small posture adjustments and exceeded the deviation threshold.
Next, I tried a bumpless takeover that follows the live state during takeover and gradually transfers control ownership at low weight.
With this method, the worst deviation during the frozen hold was about 0.00045 rad, confirming a stable takeover.
After that, for the full-weight takeover, I used the right-arm pose acquired just before takeover as a fixed anchor.
Representative results were as follows.
| Metric | Result |
|---|---|
| Maximum weight | 1.0 |
| Worst velocity | approximately 0.244 rad/s |
| Worst deviation | approximately 0.024 rad |
| Final deviation | approximately 0.017 rad |
| Result | PASS |
Velocity Spike Caused by the Measured-State Latch
After reaching the task-ready pose, I tried saving the measured joint state as the new hold target.
However, a tracking error of about 0.07 rad remained between the commanded target and the actual measured pose.
Because the command target was instantaneously changed to the measured state while the weight was 1.0, a velocity spike occurred in the right elbow.
previous command:
  captured target

new command:
  measured state

command discontinuity:
  approximately 0.07 rad

observed elbow velocity:
  approximately 0.44 rad/s
As a result, the software safety gate triggered and the arm weight was released.
After the fix, I changed to a scheme that keeps publishing the same captured target during the task-ready hold.
HOLD_TARGET_POLICY:
  CONTINUOUS_CAPTURED_TARGET

MEASURED_STATE_LATCH:
  DISABLED
With this fix, the following dry-run sequence succeeded.
Normal standing
  ↓
captured task-ready pose
  ↓
continuous arm hold
  ↓
scripted empty-air hand close
  ↓
hand restore
  ↓
controlled arm return
  ↓
normal weight release
This failure showed that on a real robot, 'making the current value the target' is not necessarily safe.
When the control weight is high, switching the target itself becomes a step command.
Open-Hand Proximity with an Empty Bottle Placed
Next, I manually placed an empty lightweight plastic bottle and ran a proximity test, moving to the task-ready pose without closing the hand.
The conditions were as follows.
bottle:
  empty lightweight plastic bottle

pose source:
  manual measurement

hand:
  open

hand command:
  none

contact:
  not intended

perception:
  not used
Representative results were as follows.
| Metric | Result |
|---|---|
| Worst arm velocity | approximately 0.313 rad/s |
| Worst tracking error | approximately 0.085 rad |
| Proximity ready | Yes |
| Hold completed | Yes |
| Return to start | Pass |
| Hard fault | No |
| Soft fault | No |
| Final arm error | approximately 0.0010 rad |
This is an open-hand proximity result for manual nominal placement.
It does not imply any of the following.
- camera-based approach
- contact grasp
- object retention
- object lift
- autonomous manipulation
First Model-Derived Command on the Real Robot
I first verified the Stage 2 model output as a shadow target.
Then, in a no-object condition, I sent the real hand a closing-only command limited to a maximum of 0.02 normalized motor units.
Stage 2 model:
  model_100

observation:
  live hand state
  + explicitly labeled nominal geometry

controlled coordinates:
  four fingers

thumb:
  held current

direction:
  closing only

maximum delta:
  0.02

object:
  none
The generated bounded delta was as follows.
[-0.0141,
 -0.0200,
 -0.0200,
 -0.0200,
  0.0000,
  0.0000]
Command reader match, ramp, hold, and restore were all completed.
However, the observed state change was only about 0.001 to 0.002, and the finger motion was not clearly visible to the naked eye.
Therefore, I treat this result as follows.
model inference:
  passed

DFQ projection:
  passed

bounded command publication:
  passed

restore:
  passed

effective grasp:
  not established
The command path working and a practical grasp being established are separate results.
Integrating Real Stage -1 and the Stage 2 Model Command
Finally, I ran the validated Real Stage -1 arm hold and the bounded Stage 2 model-derived hand command in the same sequence.
Normal standing
  ↓
captured Real Stage -1
  ↓
continuous captured-target hold
  ↓
bounded Stage 2 model hand command
  ↓
hand restore
  ↓
controlled arm return
  ↓
normal arm weight release
Representative results were as follows.
| Metric | Result |
|---|---|
| Arm command reader | Matched |
| Hand command reader | Matched |
| Arm ready | Yes |
| Stage 2 command completed | Yes |
| Hand restore completed | Yes |
| Return to start | Pass |
| Hard fault | No |
| Soft fault | No |
| Final arm error | approximately 0.0005 rad |
| Final hand restore error | 0 |
This is the result of sending the Stage 2 model-derived command to the real robot.
On the other hand, the Stage 1 actor does not yet directly control the real arm.
Real Stage -1 is a reviewed scripted transition using the captured native pose.
Offline Design of the +3 cm Lift Target
As the next real-robot primitive, I designed offline a target that raises the hand center vertically by 3 cm from the captured task-ready pose.
Using the official URDF, a numerical Jacobian, and damped least squares IK, I corrected only the four right shoulder / elbow joints.
The wrist joints are fixed at the captured pose values.
desired translation:
  x 0
  y 0
  z +0.03 m
The results were as follows.
| Metric | Result |
|---|---|
| Requested lift | 0.030000 m |
| Actual lift | 0.029994 m |
| Endpoint position error | approximately 0.015 mm |
| Z error | approximately 0.006 mm |
| Maximum XY drift | approximately 0.014 mm |
| Jacobian rank | 3 |
| Condition number | approximately 4.13 |
| Maximum joint correction | approximately 0.0633 rad |
| Predicted maximum velocity | approximately 0.0162 rad/s |
| Joint limits | Pass |
| Waypoint convergence | Pass |
The main joint correction was about -0.0633 rad on the right elbow.
This result is an offline kinematic candidate.
The following have not yet been verified.
- real actuator tracking
- self-collision
- support-rack clearance
- table clearance
- cable interference
- object load
Before using it on the real robot, a dry test in a no-object / open-hand condition is needed first.
Main Pitfalls Encountered This Week
1. Integration Can Fail Even with Strong Modular Policies
Even with Stage 1 at 768/768 and Stage 2 at 766/768, the first integrated RandPos was 428/768.
Individual policy success does not guarantee compatibility of the handover state distribution.
2. Do Not Lose Coordinate Semantics Midway
Even if Stage 1 is object-relative, if the subsequent ingress returns to nominal joint-space, the system as a whole is not object-relative.
3. Do Not Extrapolate the Local Jacobian Over a Wide Range
The local Jacobian is reliable only around that pose.
A correction that worked at ±1.5 cm cannot be used at ±10 cm without verification.
4. Do Not Call a Fixed-Point Improvement a Global Improvement
Gains or alignments that succeeded at a specific y=+5 cm position sometimes got worse in the wide paired evaluation.
5. The Same Seed Alone Does Not Make a Paired Comparison
In batch evaluations that include post-auto-reset episodes, the episode sequences may not match even with the same seed.
A true paired comparison requires an explicit design such as first episode per environment.
6. Exit Code Alone Cannot Determine Success
Even if the simulation application exits with code 0, there may be a traceback or a missing completion marker.
You need to check the result marker, completion marker, JSON, and episode count together.
7. Switching the Target on a Real Robot Is Itself a Command
Switching the target to the measured state while the weight is high can produce a velocity spike even if the difference is small.
Continuous targets and controlled return must be designed explicitly.
Current Status
The simulation results are as follows.
| Result level | Workspace | Success |
|---|---|---|
| Stage 1 modular | x/y ±1.5 cm | 768 / 768 |
| Stage 2 modular | Fixed nominal | 766 / 768 |
| Initial integrated baseline | x/y ±1.5 cm | 428 / 768 |
| Object-relative corrected | x/y ±1.5 cm | 748 / 768 |
| Full wide square | x/y ±5 cm | 569 / 768 |
| Practical asymmetric | x ±5 cm, y -5 to +3 cm | 648 / 768 |
Deployment / hardware integration status is as follows.
| Item | Status |
|---|---|
| Checkpoint migration to DGX Spark | Completed |
| x86 / ARM64 actor parity | Passed |
| Standalone actor inference | Passed |
| Real G1 state acquisition | Passed |
| Real Inspire Hand state acquisition | Passed |
| Official-model hand-center FK | Passed |
| Real Stage -1 right-arm transition | Passed |
| Scripted empty-air hand motion | Passed |
| Manual bottle open-hand proximity | Passed |
| First bounded Stage 2 real command | Passed |
| Combined Stage -1 + Stage 2 dry run | Passed |
| +3 cm lift target offline design | Passed |
| Real no-object +3 cm lift | Not yet tested |
| Real object grasp / lift | Not yet tested |
Next Steps
In the next real-robot verification, I will first check the offline-designed +3 cm lift target in a no-object condition.
Normal standing
  ↓
captured task-ready pose
  ↓
open-hand +3 cm lift
  ↓
captured task-ready pose
  ↓
Normal standing
If this dry test succeeds, I will next consider a minimal grasp and lift using an empty sealed lightweight plastic bottle.
manual central placement
  ↓
captured pregrasp
  ↓
bounded scripted closure
  ↓
short hold
  ↓
maximum +3 cm lift
  ↓
return bottle to table
  ↓
hand restore
  ↓
arm return
For the first object lift, I will not use a filled bottle or a 0.62 kg payload, and will proceed step by step starting with an empty lightweight plastic bottle.
Summary
In the previous article, I built Stage 1 Safe Approach and Stage 2 Grasp / Lift for the 0.62 kg bottle separately and confirmed they can be connected via controlled ingress.
This week, I integrated the learned Stage 2 and got grasp / lift / retention working under the nominal condition.
I then ran the integrated RandPos evaluation at x/y ±1.5 cm, and the initial success rate was 55.73%.
The cause was not policy performance: Stage 1 was object-relative, but ingress and lift returned to fixed nominal joint-space targets.
Using the measured local Jacobian to correct both ingress and lift according to the bottle offset raised the success rate to 97.40% without additional PPO.
I also extended the workspace with the Stage 0 coarse bias.
The full x/y ±5 cm square gave 74.09%, but a prospective evaluation of the practical asymmetric workspace, x [-5,+5] cm and y [-5,+3] cm, achieved 648/768, 84.375%.
After fixing the simulation milestone, I migrated the checkpoints to DGX Spark and confirmed that the deterministic actor outputs of Brev x86 and DGX Spark ARM64 agree within 1e-6.
On the real robot, I verified step by step: official-model FK, Real Stage -1 from Normal standing to the task-ready pose, continuous arm hold, scripted empty-air grasp, manual bottle proximity, and the first bounded Stage 2 model-derived command.
However, object grasp / lift on the real robot has not yet been performed.
The current status is as follows.
By combining object-relative geometric correction with frozen PPO policies, we achieved 84.375% formal integrated success in a bounded randomized workspace. We also migrated the checkpoints to DGX Spark and confirmed, on the real G1, the task-ready transition and the first bounded Stage 2 model-derived hand command.
These results come from a hybrid system combining learned policies, a geometric controller, and supervisory control, not from pure end-to-end RL.
Next, after verifying the offline-designed +3 cm lift target without an object, I plan to move on to a minimal supervised pick-and-lift with a lightweight empty bottle in a fixed standing posture.
I will not treat high simulation success rates as real-robot performance, and will proceed by verifying observation semantics, action mapping, contact conditions, and safe return behavior one at a time.